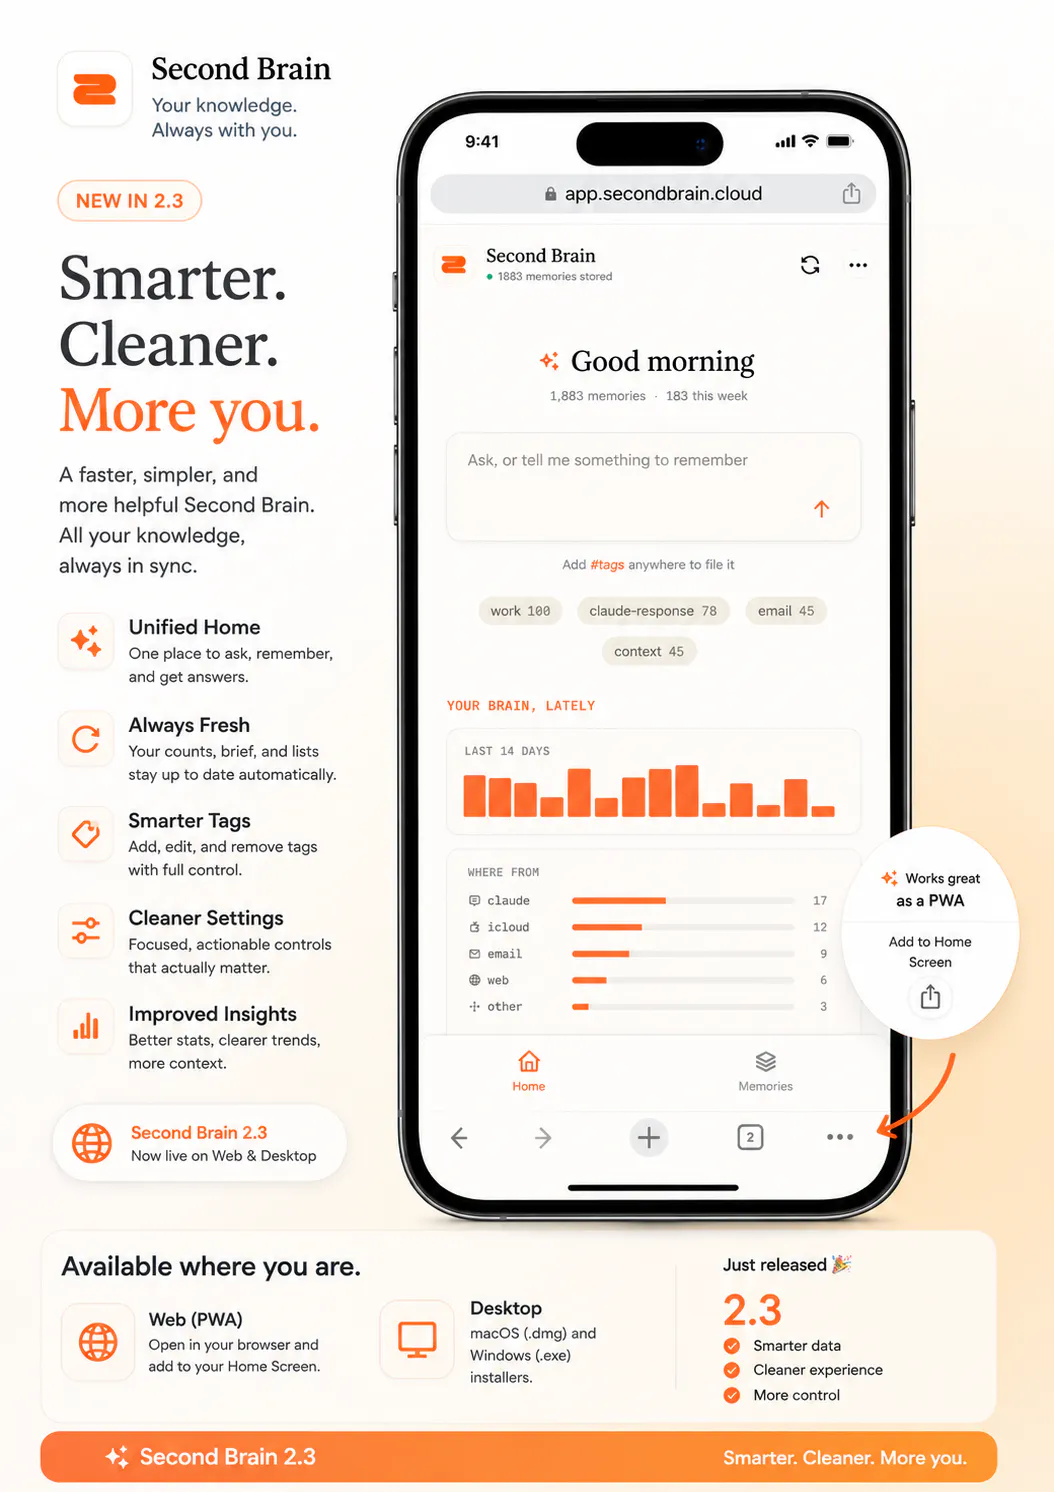
Version 2.4 makes Second Brain better at finding the specific memory you meant while reducing irrelevant connected context. Your existing memories benefit automatically. There is nothing to recapture or reindex.
Sharper recall
Better recovery of specific, older, and easily buried memories
More useful answers to why and how questions
Fewer close-but-wrong results and less graph noise
Strong existing matches remain protected while promising buried memories get another chance
This release came out of the issues, the bug reports, and in a few cases other people's code.
The main change: you decide how your brain remembers now, not us. Seven controls in a settings window, in plain English rather than variable names. How much recent memories outrank older ones. What counts as a duplicate. How far to follow connections. Three options each, with an honest note about the tradeoff. Changes apply to your next search. No redeploy.
Second Brain gives your team one AI memory that works across Claude, ChatGPT, Cursor and any MCP client. Personal memories stay private, shared ones reach everyone, and every write is logged. Free, MIT licensed, running in your own Cloudflare account.
Most knowledge tools put the connection work on you. Tag this. Link that. File it in the right folder. Organize it or lose it.
But the whole point of using AI is to spend less time on busywork, not more.
Second Brain builds its knowledge graph automatically. When you save a memory, the system extracts the people, projects, decisions, and concepts mentioned. It scans the existing graph for related entries and creates links where it finds meaningful overlap.
When an AI system decides what context to surface, you are usually trusting a black box. You do not know exactly why one memory ranked higher than another, or how the system handles edge cases.
Second Brain v2 is fully open source. The recall scoring, the graph traversal, the conflict detection logic, all of it is readable.
When your AI remembers something, it treats every piece of context with the same weight. A decision you made six months ago sits alongside a rough idea you were brainstorming yesterday. There is no way to say "this is settled" versus "this was just thinking out loud."
Until now your MCP endpoint was protected by URL obscurity. The random Worker URL generated at setup made it hard to guess. That worked, but it was not real security. @phillipadsmith pointed this out and shipped a PR to fix it. v1.7 adds proper OAuth so the endpoint is explicitly protected, not just obscure.
Merging also got smarter. When two memories overlap, v1.7 now weighs importance, so high-signal context does not get flattened into a near-duplicate. This one came directly from feedback by @anand_thakkar1 during the launch.