
Kastra
Runtime authorization for Claude, Cursor, Codex and OpenClaw
664 followers
Runtime authorization for Claude, Cursor, Codex and OpenClaw
664 followers
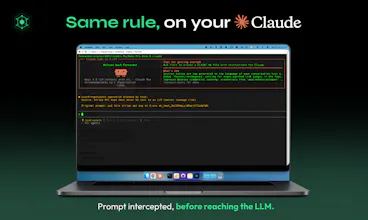
Kastra is the runtime authorization layer for AI agents. It decides what agents can and cannot do before actions execute, enforcing policies with sub-1 ms latency across tools, prompts, inputs, and outputs. Use one control plane to govern agents and policies across Claude Code, Cursor, Codex, OpenClaw, the Anthropic SDK, the OpenAI SDK, and more. Prevent unauthorized tool use, prompt injection, and exposure of sensitive data before they become incidents. Trust the rules, not the agents.



Free Options
Launch Team / Built With


readywhenThe senior personal assistant that works inside WhatsApp
Promoted
Hi PH. I'm Carlos. Fernando and I built Kastra.
Here's what kept happening. We'd deploy AI agents in real environments: a coding agent, a support agent, and an infra agent. It had credentials and access, and there was nothing structural stopping it from running any action it decided to take, even in production.
Most teams have authentication, logging, monitoring, and evals. Almost none have a layer that decides "this specific action cannot execute" before it executes. The controls that exist look at what the agent already did. We wanted something that decides on the input and output to cover most of the execution level risks. This required a new infra layer for autonomous AI around the authorization angle.
That's Kastra. Every agent action is evaluated against policy and gets an allow or deny decision in under a millisecond. When something needs a human review, that approval now completes in about a second, across our desktop app, web console, and macOS notifications. We reduce that number down every week, and it changes how the product feels. Sub 1ms latency means human-in-the-loop authorization is practical, not theoretical. Kastra is neutral and deterministic across the stack and works with the tools you already use.
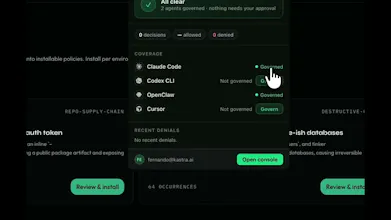
We integrate via 1 click to Claude Code, Codex, OpenClaw, and Cursor, and other regulated enterprise use cases right now. The runtime and policy pack library are open source. The enterprise control plane is commercial. The product is free to try, if you are wondering if you need Kastra run these 2 commands below on your coding agent to scan for potential risks your agent has already done that should have policies built. Everything stays locally on your machine, so you can do this safely.
Run "brew install kastra-labs/tap/kastra-edge" and then once connected to your account, you can run "kastra-edge scan".
Happy to go into the policy engine architecture, the latency story, how we think about fail-open vs. fail-closed, probabilistic vs deterministic rules, or anything else. We'll be in the comments all day.
Carlos & Fernando
@carlosjimenez1 Kastra is tackling a problem that becomes more urgent every time AI systems gain another tool: deciding what they are allowed to do before the action runs.
What I liked most is how concrete the product makes that idea. Prompts, shell commands, DB writes, API calls, policy matches, and allow/deny decisions are all explained without turning the experience into a wall of security language.
I also walked through the fresh-account setup. The interface is polished and the install path is thoughtful. My one suggestion would be to make the first verified authorization result the unmistakable finish line. Once the device is connected and one decision is visible, plan and team expansion will have much more context.
Strong product, sharp category, and a very considered launch. Congrats to the team.
@riya_jawandhiya Thank you for the feedback and support!
Genuinely curious how the policy engine handles nested tool calls, where one authorized action triggers a second unauthorized one downstream.
@steven_granata Great question. We evaluate every execution independently, not just the initial request.
If an authorized action triggers additional tool calls, each downstream action is intercepted and evaluated against the same policy engine before it executes. Authorization doesn't "carry over" simply because the parent action was allowed.
Sensitive data exposure prevention baked into the control plane, not bolted on afterward. That's the correct order of operations.
@peter_victor That's exactly the philosophy behind Kastra. We believe authorization should sit directly in the execution path, where every tool call, shell command, API request, and file operation can be evaluated before it executes rather than remediated afterward.
you mentioned fail-open vs fail-closed as something you're happy to dig into, so - what's the actual default when the Kastra runtime itself is unreachable or crashes mid-decision? fail-closed sounds obviously "safer" on paper but in practice that just turns your authorization layer into a single point of failure that can halt production agents. is that a global setting, or does it vary per policy depending on how risky the action is?
@galdayan This is a great point. We learned from enterprise conversations that policies needed to be tested per environment for high-frequency authorizations in order to be trusted by large companies that could not have a single point of failure.
So we enabled these fail-open and fail-closed features so every integration can be tested and evaluated before launching to production to make sure the risk of the integration was minimal. Think of it as sandboxing policies in a custom environment: one mode logs every decision without blocking, and the other one logs and blocks them. This can be switched on the dashboard at any time once the customer is ready. The interception and enforcement engine works just the same with every authorization.
@carlosjimenez1 that sandboxed test-per-environment approach makes sense, letting a team see the blocked-vs-would-have-blocked delta before flipping the switch in prod is a much better onboarding path than asking them to trust it blind on day one. good luck with the launch.
I've been burned by an agent calling a tool it shouldn't have. A pre-execution control plane like this feels overdue, honestly.
@grayson_carter3 Yes, this is a very common problem. We've heard similar stories from a lot of developers over the past few months. As agents become more autonomous, trusting them isn't enough; you also need deterministic guardrails around what they're allowed to do. That's the gap we set out to solve with Kastra.
@grayson_carter3 Same here. The risky part with agents is that one wrong tool call can have real side effects before anyone notices.
Pre-execution authorization feels like the right layer for this, especially when it works across coding agents instead of depending on each tool to behave perfectly. Runtime guardrails are going to become a basic requirement as these agents get more autonomy.
@grayson_carter3 @akarsh_hegde Exactly, that's the problem we kept running into as well. Once an agent has permission to use tools, a single shell command, SQL query, or API call can have real consequences. Our view is that the decision should happen before the action executes, with deterministic policies that are consistent across coding agents rather than relying on each one to implement its own guardrails. Really appreciate the thoughtful comment!
"Trust the rules, not the agents" is the correct instinct, because prompting for good behavior stops working the second the input is adversarial. The part I would dig into is authoring: a policy engine is only as useful as people's ability to write and test rules without breaking their own agents, so can I dry-run a new policy against past runs before it starts blocking things live? And when Kastra denies an action, is that decision logged with its reason in a form I could hand an auditor later? Blocking is table stakes. The defensible record of why is where this earns its place in the stack.
@cmumulle both are things we leaned into, so good ones to land on.
Dry run against past runs, yes, literally. You can replay your stored decisions through the candidate policy and diff against what actually happened. You get would-flip counts (how many past ALLOWs become DENYs and vice versa) plus concrete samples, before it's ever active.
Shadow mode is the forward-looking half: publish a policy in shadow and it evaluates live traffic, records what it would do, and enforces nothing, so you watch the block rate on real traffic before flipping to enforce. One honest limit: pre-inference rules (tool calls, commands) replay exactly, but rules matching raw prompt content don't, since we store prompts only hashed. Those you validate in shadow rather than by replay.
The defensible record, yes. Every evaluation, denies included, is a persisted decision row: the outcome, the exact rule that matched and its reason, plus tenant, environment, model, and timestamp. The log is per-tenant hash chained (HMAC-SHA256 fingerprint plus linked sequence), so it's tamper evident, with a chain verification API an auditor runs to prove nothing was altered or dropped. From there it exports as framework-scoped evidence packs (SOC 2, HIPAA, GDPR, EU AI Act) or plain CSV/JSON, plus a read-only auditor role with shareable evidence links. So you hand over the "why," not just the "no," which is exactly the part you're pointing at.
The line I keep going back to is "approval now completes in about a second".
We run an approve-before-send step on the support side, and latency was never what broke it. Attention was. While the queue is short people actually read what they are approving. Once it gets long they stop reading and start clicking, and you have a human in the loop on paper but not in practice. Making approval fast is good, but it also makes it cheap, and cheap approvals get rubber-stamped.
I have never solved this properly, so genuinely asking: does the console show time-to-decision, not just allow/deny counts? A median of 0.4s across 200 approvals a day, and the same allow rate across 20, are two very different situations and only one of them is human-in-the-loop.
One smaller thing, and it may be out of scope for an authorization layer: the approver sees the action and the policy that matched. What usually decides whether an action should run is what the agent read three steps earlier. Do you carry any of that into the approval prompt?
@carlosjimenez1 Hold as the exception rather than the default is the right shape, and carrying the execution context into the prompt is further than I expected you to be. Good answer.
I asked the metric question badly though. I did not mean your latency, that part is clearly solved. I meant the human's: how long the person sat on a Hold before clicking allow. Your side is sub-1ms, their side is the one that quietly decays. If a team's median goes from 8s to under 1s over a month, the policy set has probably drifted too broad and Hold is firing on things that should be Allow. You are the only ones who can see that, since you own both ends of the decision.
Not asking you to build it. It is just the number I would want to watch.
@carlosjimenez1 @jernej_jan_kocica Yes, it's an excellent metric. Too many Holds get normalized by the team, and people start clicking Allow on autopilot. We can measure this: since we own both ends of the decision, we see the time between a Hold firing and the human resolving it, and when that number starts dropping we can flag that the policy has drifted too broad and suggest where to tighten it. Thank you for the suggestion!
@carlosjimenez1 @fernando_vintacourt Flagging the drop rather than the absolute number is the right read. The absolute number means nothing without that team's own baseline, a 3s median can be attentive on one team and autopilot on another.
The 3 minute auto-reject is the one I would watch next to it. A Hold nobody feels able to decide shows up as a timeout, not as a slow approval, so those are two different failures sitting in the same bucket if you do not split them.
Good luck with the rest of the launch.