
Kastra
Runtime authorization for Claude, Cursor, Codex and OpenClaw
664 followers
Runtime authorization for Claude, Cursor, Codex and OpenClaw
664 followers
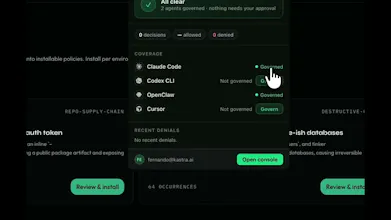
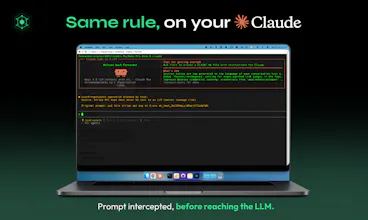
Kastra is the runtime authorization layer for AI agents. It decides what agents can and cannot do before actions execute, enforcing policies with sub-1 ms latency across tools, prompts, inputs, and outputs. Use one control plane to govern agents and policies across Claude Code, Cursor, Codex, OpenClaw, the Anthropic SDK, the OpenAI SDK, and more. Prevent unauthorized tool use, prompt injection, and exposure of sensitive data before they become incidents. Trust the rules, not the agents.




Carlos, the deterministic engine is the part that matters for my world. I sell AI into healthcare, and "the agent usually behaves" is not a line you can put in front of an auditor or a BAA, since a probabilistic guardrail is a suggestion while a deny decision in the execution path is a real control.
Where I would push: preventing exposure of sensitive data assumes you can recognize it first. Is a policy written against the tool or endpoint, or can it key off the content itself, say a rule that blocks any output carrying patient identifiers no matter which tool produced it?
And does every allow or deny land in an audit trail I can hand to a compliance review? In regulated work, proof that the control fired is worth as much as the control.
The deterministic claim holds right up until the tool is generic.
Denying delete_file or write_prod is the easy case, because the intent sits in the tool name and you can rule on it in under a millisecond. But a coding agent needs a shell. Once bash or run_command is permitted, the dangerous action stops being a tool call and becomes an argument string, and the engine is no longer authorizing an action, it is parsing arbitrary shell to predict one. That is the part that cannot be made deterministic.
It is also where the real incidents will come from, because nobody takes the terminal away from the agent. They deny it the scary sounding tools it was never going to reach for anyway.
How does a policy express that boundary? Can you constrain inside a permitted generic executor, or does allowing bash effectively allow everything downstream of it?
@carlosjimenez1 That is the answer I was hoping for, and it moves the question down a level rather than closing it.
Inspecting the command and its arguments works when the dangerous thing is visible in the string. The cases I would worry about are the ones where it is not. A base64 blob piped to sh, a curl to a URL that is fine today, a variable resolved from the environment at run time, a script the agent wrote to a file one step earlier and now executes by path.
In all of those the literal argv is harmless and the effect is not, so the check either resolves the indirection or it is matching on surface text.
Where does Kastra draw that line?
@abdullah_javaid3 This is the part we spent the most time on, so it's fun to talk about.
The principle we settled on: a command check should judge what's written, not predict what will happen. Reading argv is decidable; predicting the effect of arbitrary shell isn't. The line sits there.
On the readable side, matching anchors on the operation rather than its spelling. The same rm -rf trips whether the binary is path-qualified (/bin/rm -rf) or the flags are reordered (rm -fr), across every surface the agent uses.
Your four cases sit on the other side, where the string is honest but the effect is hidden: base64 | sh encodes the payload, $VAR resolves only at expansion, a safe URL can turn hostile later, and write-then-run splits intent across two calls. We don't claim to see through that, what covers it isn't a smarter parser but a different control: high-blast-radius operations get a hold and a human regardless of how the string reads, and every executed call lands in a tamper-evident, hash-chained audit log, so what we can't decode up front is still recorded and provable after.
@fernando_vintacourt Fair split, and the hash chained log is the right backstop. The part I would push on is that it is a different class of control than the tagline promises.
A log is detection. It proves what happened after the credential was already spent. Prevention is what stops the call. So for the four opaque cases you are not preventing, you are recording, and those two things sell to different buyers with different risk appetites.
Which puts all the weight on the blast radius classifier. If it rates the command, opacity beats it, because you cannot rate the radius of a payload you cannot decode. If it rates the context instead, prod credentials in scope, egress allowed, write access outside the workspace, then opacity stops mattering and the guarantee survives.
Which is it? And does an undecodable construct escalate on its own, or does it pass when the surrounding context looks ordinary?
Shell is where I'd expect this to get hard. Our own gate covers browser writes and it holds up because the surface is tiny, a selector and a URL allowlist. Once the agent has a terminal the dangerous action stops having a name: it isn't rm, it's a git checkout that throws away an hour of work, or python -c doing whatever it likes. Does the engine evaluate the tool call and its arguments as a string, or do you parse the command, and what happens with bash -c and heredocs?
@dipankar_sarkar You’re right, shell safety cannot be reduced to an executable allowlist. We evaluate the full invocation, not just the command name, and normalize/parse common command families so policies can reason about operations like destructive Git changes rather than only strings.
Opaque wrappers such as bash -c, python -c, heredocs, pipes, and chained commands are treated conservatively: they can be inspected recursively, held for approval, or denied. We also don’t pretend arbitrary shell code can always be perfectly understood statically, so downstream actions are authorized independently whenever they surface.
Congrats team! 🚀 Runtime authorization before execution is the piece most agent stacks are missing, and covering Claude Code, Cursor, and both major SDKs from one control plane is a smart wedge. Quick technical question: how do you intercept actions across such different runtimes? Is it a proxy sitting between the agent and its tools, SDK-level hooks, or MCP middleware? Curious whether an agent could bypass enforcement by shelling out directly, and how Kastra closes that gap. Excited to dig into the docs!
@waqas_baloch4 Thanks, we use multiple interception points depending on the runtime. Model traffic can be governed through SDK integrations or a proxy, while tool execution is intercepted through native runtime hooks, local middleware, and MCP where applicable.
Shell bypass is exactly why SDK-only enforcement is insufficient. For coding agents, Kastra runs a local execution layer that evaluates shell, filesystem, and tool actions near the point of execution. If an agent shells out directly, that action still needs to pass through the local gate rather than inheriting trust from the original model call. The broader principle is that every execution surface must be governed explicitly. We never assume that controlling the prompt or SDK automatically controls what the agent does next.
This is the unglamorous layer everyone is about to need. The moment you let Claude or Codex actually run things, "what is this agent allowed to do right now" stops being a nice-to-have. Runtime is the key word for me. Static permissions are easy, but authorizing per action while the agent works is the hard part. How do you handle an agent that needs to escalate mid-task without a human sitting there approving every step?
@ben_kahan Yes, it's a required layer, and it shouldn't come from Anthropic or OpenAI themselves. It should be a neutral layer that blocks sensitive data from ever reaching them, because that's the only way to be sure the data stays secure.
Allow and Deny are automatic at runtime: if a policy says something should be blocked, it's blocked right away, no human involved. Only when the effect is Hold do we notify a person, via OS notification, email, Slack, and so on, that something needs approval, and if that request times out it fails closed to Deny.
The AI also learns that it can't perform the action, and through our MCP integration it can see exactly why it was blocked, so it can adjust (if possible) instead of just hitting a wall.
The "existing controls only look at what the agent already did" line is the real gap — logging and evals are post-hoc, and the irreversible action already happened by then. Sub-1ms allow/deny I buy. The piece I'd want to understand is what routes an action to human-review vs auto-allow, because that classification is the hard part: when I give Claude Code broad access the legit action space is huge and situational. Auto-deny runs brittle and breaks a real task mid-run; escalate too much and I rubber-stamp the ~1s approvals until I'm not really reviewing. Is that routing static rules on tool + args, or does it reason about intent against the current task? And input-layer injection — how do you flag the instruction that reads as a perfectly normal one inside a 1ms budget, without an LLM in the loop?
@narek_keshishyan That's exactly the tradeoff we think about. The runtime path is deterministic; we don't put an LLM in the authorization loop. Policies evaluate things like the tool, operation, arguments, environment, identity, and execution context to allow, deny, or require approval.
To avoid approval fatigue, teams typically start in shadow mode and then enforce around high-risk actions like production writes, destructive SQL, secret access, and privileged commands. The goal is to review the exceptions, not every action.
For prompt injection, our focus is on controlling the actions an injected prompt could trigger, rather than trying to semantically classify every prompt within the runtime path.
@carlosjimenez1 Shadow mode answers which actions to gate. What I'd want to know is whether the baseline survives enforcement. You collect it while the agent runs unenforced, then you turn the gate on and the agent starts routing around denials: retrying differently, decomposing one blocked action into two allowed ones. The distribution you calibrated against isn't the one you're now policing.
Related: "review the exceptions, not every action" holds while exception volume stays low, but exception rate tracks how novel the work is. Exceptions spike exactly when the work is unfamiliar, which is when you can least afford to judge them fast.
Does the policy set get recalibrated against post-enforcement traffic, or is shadow mode a one-time setup step?
@narek_keshishyan That's a great point. We don't think of shadow mode as a one-time calibration step—it's something teams can keep running alongside enforcement to observe behavior and refine policies as workflows evolve continuously. You're also right that agents adapt. That's why our goal isn't to model every future behavior perfectly, but to enforce deterministic boundaries around high-risk actions while giving teams visibility into how those behaviors change over time. The policies should evolve with the agent, not stay static.
@carlosjimenez1 Continuous rather than one-time makes sense, and "policies evolve with the agent" is the right posture.
One asymmetry in that loop worth naming: once enforcement is on, allowed actions produce outcomes you can learn from and denied ones produce nothing. A block that was correct and a block that was a false positive look identical afterwards, because neither ever ran. So the traffic teaching you where the boundary belongs is exactly the traffic that stayed inside it, and over-tight policy becomes the failure mode with no feedback signal attached. Do you do anything with the denied set, sampled replay in a sandbox, or a way for someone to mark a denial as wrong that feeds back into the policy?
Congrats on the launch. Deciding before the action executes, rather than reviewing what already happened, is the right place to sit.
The thing I would want as a builder is every denial landing as a structured event I can line up with the agent's own trace. When an agent quietly stops making progress, the hardest case to debug is not knowing whether it hit a policy or just reasoned itself into a dead end. If the authorization decision and the step that triggered it share an id, that is a five minute answer instead of an afternoon.
@paul_crinigan Thanks! We think that's a key part of the developer experience. Every authorization decision includes structured metadata and a request ID so it can be correlated with the agent's execution trace. When something stops, you should be able to answer "was this a policy decision or an agent decision?" in minutes, not hours.