
MartinLoop lets you give coding agents real software jobs without babysitting every step. Finally trust coding agents with real software work.
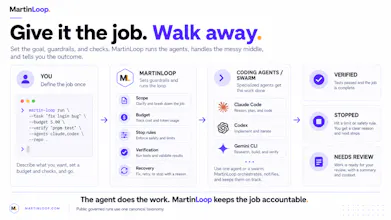
Give an agent the job and walk away. MartinLoop keeps it focused, bounded and accountable with budgets, stop conditions, verification, recovery and a clear outcome when the run ends.
Keep Claude Code, Codex, Gemini CLI and your existing workflow. Open-source core, CLI + MCP, model-agnostic by design.





Free
Launch Team / Built With


Viktor.comAn AI coworker that actually does the work
Promoted


A small rule that catches a lot of fake progress: if the agent can't explain what changed since the last attempt in one sentence, it probably should not get another retry yet. That sounds strict, but it saves a lot of budget from "busy" loops that only reshuffle the same failure.
Beginner-friendly agent UX is mostly about predictable stop states. People forgive a small failure if the tool says what happened, what it checked, and why it stopped. They lose trust when the run keeps going with no new signal.
Small update for launch-day testers: the fastest way to try MartinLoop is now:
npx martin-loop demo
The feedback I want most is simple: after an AI coding run fails, what proof would make you trust the next attempt?
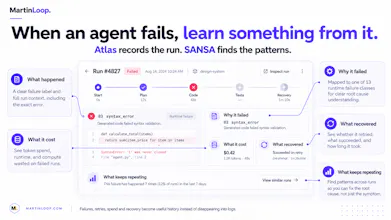
One thing launch day made painfully clear: people don't really want smarter loops, they want safer ones. The trust breaks after the second or third retry when nothing changed and the system keeps spending anyway. The most useful rule we've found is simple: before another retry, show what changed. If nothing changed, stop.
One thing we've learned building this: a budget cap by itself doesn't save you. The expensive runs usually happen after the first failure, when the agent keeps trying without any new evidence. The rule that matters most is simple: before another retry, show what changed. If nothing changed, stop. If anyone here has a real agent failure story, I'd genuinely love to hear it because those cases shape the product more than feature wishlists do.
One thing we’ve learned building this: a budget cap alone doesn’t really save you. The ugly runs happen after the first failure, when the agent keeps trying without any new evidence.
The rule that seems to matter most is simple: before another retry, show what changed. If nothing changed, stop.
If anyone here has a real agent failure story, I’d genuinely love to hear it. Those stories shape the product way more than feature wishlists do.
A pattern we keep hearing from teams is that the expensive part is rarely the first agent mistake. It is the quiet retry loop after the first mistake, where nothing meaningful changed but the system keeps spending anyway. The most useful rule we have found is simple: before another retry, show what changed. If nothing changed, stop the run. That has shaped MartinLoop more than any benchmark has.