
Cortex is an open source API knowledge layer that turns OpenAPI, AsyncAPI, GraphQL, gRPC, and OpenRPC specs into interactive documentation, typed SDKs in 11 languages, and MCP servers for AI agents.


Hey Product Hunt 👋
I’m Nick, and I built Cortex because being an engineer in the AI era means your APIs increasingly need to serve two very different users: developers and AI agents.
But supporting both often means doing the same work twice. You build documentation and SDKs for developers, then create separate MCP tools and context for agents.
Today, these pieces are usually maintained separately. They drift out of sync, create duplicate work, and leave AI agents trying to understand your API from incomplete or outdated context.
Cortex makes your API contract the source of truth.
Give it your OpenAPI, AsyncAPI, GraphQL, gRPC, or OpenRPC specs, plus Markdown, and Cortex generates:
📚 Interactive documentation for developers
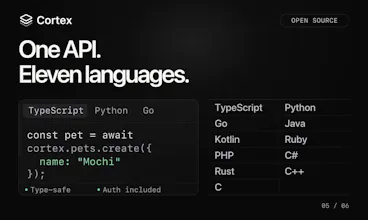
⌨️ Typed SDKs across 11 languages
🤖 MCP servers with typed tools and grounded API context
Everything is open source and MIT licensed. You can customize the templates, publish the SDKs wherever you want, and host the generated documentation yourself.
The idea is simple: define your API once, then give every developer and every agent the interface they need to actually use it.
Check out the open source repo at https://github.com/cortex-docs/c...
I would love feedback from teams building APIs, SDKs, developer tools, and agent integrations.
What would make Cortex more useful in your workflow?
Report

@nick_csu Love the idea of keeping one source of truth for both developers and AI agents. Really smart approach 👏
Report

@nick_csu generating a both type of MCP and SDKs tools the same requirement is really interesting, it seems like a smart way to avoid maintaining distinict docs for developers and agent.
how much setup are needed to go from an existing OpenAPI spec to a eork on MCP server??
Report

@nick_csu this is super cool, i was looking for something like this exactly...
Report

The SDK generation is that your own work or are you using the one from OpenAPI ? The C# generation from openapi is a a messy code bloat.
Report

@nick_csu the idea of interactive API docs sounds sweet, for me, the way i'd use this is via mcp, being a SWE myself, and i find this solution useful personally, gonna try it out, thanks!
Report
Maker
@therayess Thanks! I'm glad you think the MCP approach is useful. Let me know how you find it when you try it out!
Report


we run a small mcp server, 28 tools, and the part that took longest was not the types. it was the descriptions.
two of ours read "fetch before prospecting to skip duplicates" and "stored as DRAFT, not sent". neither of those is in any schema. the first is an ordering rule, the second is there so the agent doesnt tell you it sent something that is only queued.
a spec gives you the shape of every call and nothing about which of two similar endpoints is the right one. for the sdk thats fine, the developer reads the page. for the agent that one string is the whole basis of the decision.
so when you generate the mcp server, what goes into the tool description? the summary field from the spec, or something else?
Report


sometimes I start with the docs but then get distracted rewriting API calls. if Cortex auto-generates integration code from specs, might save me from wandering off before everything's written up. but I always skip reading the full spec first, so who knows.
Report
Thanks for the reviews you provided; they're really helpful. It might help a lot if you could open these as separate issues on https://github.com/cortex-docs/cortex/issues so we can track and fix them