Adam Cohen is the cofounder of @Weave , an engineering analytics company that helps teams go AI-first. Before Weave, he was head of operations and sales at education software firm Top Hat and VP of operations and revenue at @Causal , which was acquired by Lucanet in 2024.







 OpenRouter
Weave Engineering Intelligence
Hey Product Hunt, I'm Adam, Co-founder of Weave!
The Problem
Coding agents send every request to one model. A one-line config change and a cross-service migration both go to the same frontier model at the same price. Teams are paying frontier rates for routine work, and the bill grows with every agent they add.
Most tools in this space follow one of two flawed approaches:
❌ Gateways – They give you one endpoint and a menu of models. You still pick the model yourself, so nothing actually gets cheaper.
❌ Manual model switching – Flipping /model mid-session breaks your prompt cache, and on long sessions the re-billed context eats the savings.
After running into this on our own agent traffic, we built Weave Router to solve it.
How Weave Router 2.0 is Different 🚀
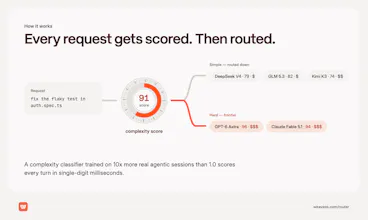
Weave Router plugs into Claude Code, Codex, and Cursor as a drop-in endpoint. It reads every request your agent makes, scores how hard it is, and sends it to the cheapest model that will get it right.
The benchmarks
We ran 2.0 head to head against GPT-6 Astra, each task run twice (pass@2).
📊 Terminal-Bench 4.0 – Tied pass rate within the confidence interval. 52% of Astra's cost. 2.2x faster.
📊 SWE-Atlas Codebase QnA – Tied pass rate within the confidence interval. 46% of Astra's cost. 2.5x faster.
Full results at weaveos.com/router.
🔹 Complexity-scored routing – A new classifier trained on 10x more real agentic coding sessions routes on task difficulty, not task type. DeepSeek, GLM, and Kimi handle the simple turns. Astra and Fable handle the hard ones.
🔹 Cache-aware switching – 2.0 tracks cache state per provider and per session. It only switches models when the expected savings beat the cost of rebuilding the cache. This is where most of the cost win comes from.
🔹 Multi-subscription routing – Use Claude models inside Codex and GPT models inside Claude Code. Route by complexity, by cost, or by whichever plan still has quota this month.
Who is this for?
If you or your team run coding agents daily, Weave Router gets you Astra-level results at about half the cost and more than twice the speed, without changing your tools.
🔗 Get started today
Try it at weaveos.com/router. Install with one command: npx @workweave/router. Source-available under Elastic License 2.0. Teams of 50+ engineers can book time with our FDEs.
how does weave handle token routing when multiple AI models are running together?
Does it support custom cost caps per project?
Do you have a VS Code extension coming?
Can users set their own preferences for cost versus speed or does Weave handle that automatically?
I have used Weave for my team and it noticeably improved our engineering output.
How does Weave decide which model is capable enough for s specific coding task?