Launching today

Translucent AI
Test infrastructure for hardware teams
4 followers
Test infrastructure for hardware teams
4 followers
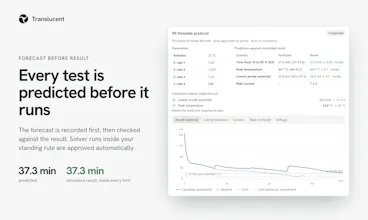
Agents choose the next physical test and run solver tests within rules a hardware team sets once. Bench tests go to a qualified person. Works with any agent. Physical tests come with a procedure and a forecast. An engineer decides whether to spend the bench time, and an operator enters the result.



Free
Launch Team / Built With


AWS Activate CreditsCredits that fuel your startup’s next milestone
Promoted
Hey Product Hunt!
I built Translucent because AI agents can now propose hardware designs faster than any lab can test them, and right now the bottleneck is the test bench. Hardware teams want agents in their workflow, but they can't hand over the bench to something whose decisions they can't trace.
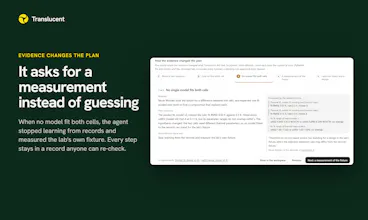
So Translucent does one job: it chooses the next physical test. The agent picks the few tests that settle a design and writes down a forecast for each before the result comes in. It runs solver tests on its own inside cost, time and run-count limits your team sets once. Bench tests always go to your engineer with a procedure attached. When the data can't support a design, the agent asks for the measurement instead of guessing. Every step goes into a record anyone can re-check offline.
Batteries are the first system. In a simulated fast-charge race with 8 experiments, Translucent found a 33.8-minute charge (10 to 80%), compared with 42.6 for Bayesian optimisation and 60 for the cell's standard charge. It stayed inside the anode-plating and 45 °C temperature limits. These results are all simulated; no physical cell has been tested yet. Next we're working on data-center hardware, robotics and power electronics.
Feedback that would help most:
1. If you run hardware tests: which tests take up the most bench time without settling anything?
2. Would your quality team accept solver runs approved by standing rules, or does every run need a sign-off?
3. What instruments and file formats should we support next?
Try the live demo: https://translucent.axcelner.com/demo/
Code and self-hosting: https://github.com/ychampion/translucent
I'll be here all day answering questions.
I also wrote up the research behind Translucent:
"Translucent: Language agents for autonomous experimental engineering."
It covers the experiments, the system we built, what the models actually decided, and where the approach still falls short.
The opportunity is to let it handle more of the investigation around those methods: understanding unfamiliar data, deciding what to measure, and working through the results.
The code and evaluation reports are public.
Paper: https://translucent.axcelner.com/research/autonomous-experimental-engineering/translucent-autonomous-experimental-engineering.pdf