
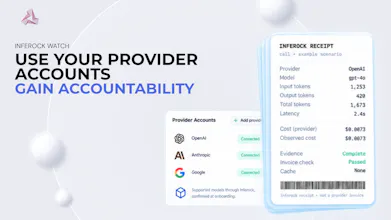
Inferock-bench is a local proxy that sits between your app and OpenAI, Anthropic, Gemini, or OpenRouter shaped calls. It captures per-call token usage, failures, and retries, then generates an independent receipt showing what you were billed and how much you're actually overpaying for.
This is the 2nd launch from Inferock. View more

Inferock
Launching today
Get free signup credits to use all available models on Inferock.
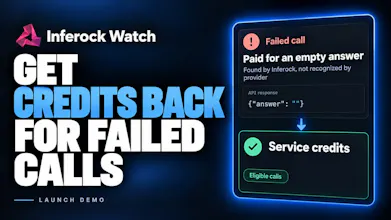
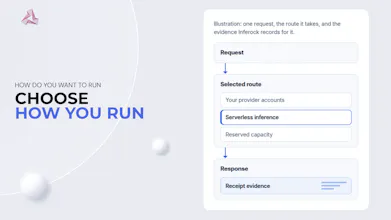
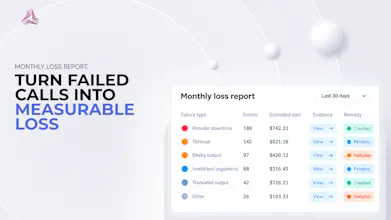
Bring your own keys: run your OpenAI, Claude or Gemini accounts, see where calls fail and what they cost, and get credits back on eligible failed calls.
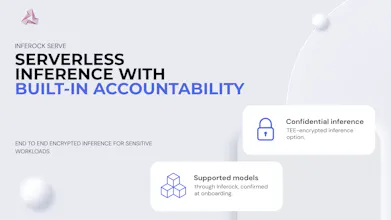
Serverless: pay-per-token LLM inference. Get signup credits to start using.


Free Options
Launch Team / Built With


Interesting launch! For the per-call receipt, I’d want to see the expected cost alongside the billed cost, plus whether a retry was billed separately. Does the receipt also show when the provider pricing data was last updated?
@adityaharish2002 Those are fantastic ideas, right now every call states its outcome, 'successful' or a myraid of failure states.
All states record the cost of that particular call. Hope that helps.
The expected cost and last updated pricing would be great additions! I'll pass them on to the team!
If you have any more questions, feel free to ask away!
Love the focus on transparency and accountability. Wishing the team great success! 👏
@chrishicken Thank you, that means a lot.
Accountability for production AI is exactly what we set out to build. If you try Inferock Watch on your own keys, we would love to hear what you think!
I have been looking for an independent auditor for LLM tokens because developer dashboards often feel a bit opaque when it comes to exact token counts.
I like the idea of getting a clear record of failed inference calls. When I’m debugging an AI workflow, knowing exactly what went wrong and what it cost would be genuinely useful.
@daniel_l_e Thanks, that debugging moment is exactly what we built it for.
Inferock Watch is free on your own OpenAI, Anthropic or Gemini keys and shows quality, latency and cost for each call, so a failed step in a workflow comes with what it cost you.
Which failures slow your debugging down the most right now?
Tracking quality, latency, and cost together sounds practical. I usually end up checking different logs and dashboards, so having one receipt for each call could help me understand issues faster.
@yolanda_c_schneider Thanks, that juggling between logs and dashboards is exactly what we wanted to end.
Inferock puts quality, latency and cost for each call in one place, along with a monthly inference performance report.
If you try Inferock Watch on your own keys, we would love to know which issue it helps you spot first.