Launching today

FastRouter.ai
Route requests to the right LLM for cost, latency & quality
623 followers
Route requests to the right LLM for cost, latency & quality
623 followers
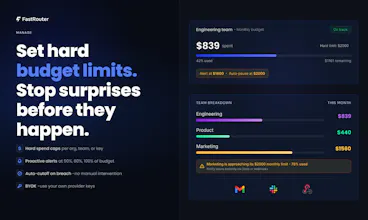
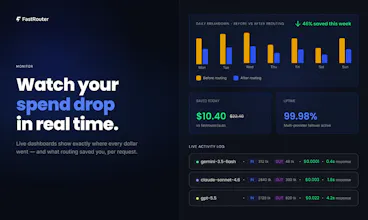
FastRouter is a unified AI gateway and control plane for developers and enterprise teams building with LLMs. It routes every request to the right model across 200+ LLMs through one OpenAI-compatible API, optimizing for cost, latency, quality, and reliability. With intelligent routing, failover, observability, and governance, teams can scale AI apps without vendor lock-in or code changes.




The first users usually seem to come from places where the problem is already being discusses. Curious if anyone has had better results from communities than from posting on their own profiles.
Many congratulations, @ritprasad , @andrej_gamser2 and team! 😊
@dhanrajchoudhary Thank you! Your support means a lot. Really appreciate it.
Awesome product, congrats with a launch and good luck!
@annmast Thank you for your message. Really appreciate it and grateful :)
@nalin_rajendran Thank you for your support. Really appreciate it and grateful!
Cost, latency and quality is three knobs where the third one does all the work and is the hardest to measure. We route across 30+ models in our own product and the thing that bit us wasn't a slow call or an expensive one, it was a small model returning something clean, confident and wrong, which passes every format check you have. So the number I'd want out of a control plane is cost per accepted output, not cost per call, because a model that's 4x cheaper and needs two regenerations just moved the bill somewhere nobody is measuring. If the quality signal behind routing is benchmarks rather than what your own users kept, it'll pick the cheap model at exactly the wrong moments.
@asadmalik901 Fully agree. The key is to score outputs against a clear defined rubric for your use case and get the actual quality score for accepted requests. FastRouter’s Custom Evaluations does exactly this and Insights too help you measure this quality alongside cost and latency, so you can choose the model that best meets your needs. As you said, benchmark scores alone are not relevant if your use cases are different.
congrats on the launch. my biggest headache is latency and failover at the same time, since we work with voice. once audio starts playing you can't quietly retry, so the fallback has to be decided before the first byte goes out. does your routing optimize for time to first token and p95 rather than the average? and if a provider dies mid stream, do you restart on another upstream or just surface the error?
@danivs10 Great questions.
1. While the order of model x provider choices to be made take into account cost and error rates, the decision to failover for a particular request is based on a combination of fixed values (e.g. when exactly to timeout) to upfront provider errors that we receive.
2. If the stream has already started and the provider errors out midway, we don't retry. We surface the error on the stream and end it.
Happy to discuss / add a feature if useful for your use case - e.g. build a configurable rule for timeout, retry, etc or anything else that may be valuable. Do reach out to us on support@fastrouter.ai.
This solves a massive headache for us. we were literally spending hours last week figuring out how to balance claude and gpt costs.
@sansa_grey Yup, figuring out when to use Claude vs. OpenAI or even other models, tracking spend, and checking quality can quickly become a job of its own. That’s exactly why we built an easy to use AI evals product; as well as proactive cost recommendations with Insights -- to help you identify when to leverage different models. Thanks for checking us out!