
Eclatira
Conversational Video Agent That Plugs Into Any Stack
599 followers
Conversational Video Agent That Plugs Into Any Stack
599 followers
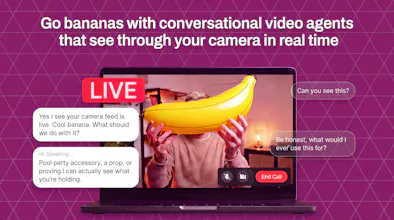
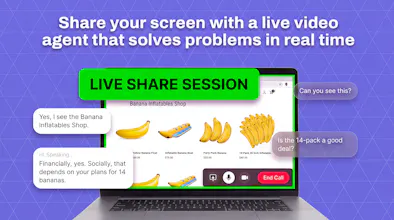
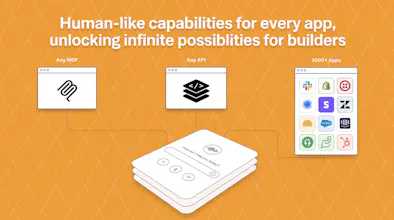
Plug real-time conversational video AI into any application. Eclatira gives developers native voice-to-voice, live vision, and full-stack execution across custom APIs, MCPs, and 3,000+ apps. Ship autonomous multimodal video agents fast.
Free Options
Launch Team / Built With


Context.devAPI to scrape anything for AI, 20,000+ developers trust us.
Promoted
Congrats. What I find unique is the merger of voices, vision and actions into one conversational engine. There's a lot of potential here for turning existing SaaS products into interactive AI experiences. Excited to see the roadmap.
@roopreddy yesss lots more to come. Really appreciate the comment!
Voice-to-voice plus real-time combined with vision feels like the future of AI assistants. Static text based assistant will start to feel outdated. Nice work. 🔥
@shubham_pratap Thank you! Absolutely that's the future
The AI can now look at the screen, talk back, and press the buttons for you haha. That's a pretty spicy combo. Nice work guys! @moad_rahali_semlali @maryam_gilsenan1 @aya_manguer
@zach_francis Thank you! Appreciate it!
@hamza_afzal_butt Thank you!! Appreciate it man!
The live vision piece is what stands out here, since most conversational agents are voice only and lose all context the moment something visual matters. I build voice AI that calls aging parents every day for Callie Care, and the thing that consistently bites us is latency the moment a tool call lands mid conversation. How are you handling barge in and turn taking when the agent is executing against an external API in the same turn, do you buffer a filler response or let it go quiet? Also curious how you keep the video agent from feeling uncanny on longer sessions.
@igorgurovich since its voice to voice, the barge in mechanisms is very different that tts stt so barge in and turn taking is handled beautifully and external tool calling doesn't make any difference in quality.
we build voice-only agents for phone calls and latency is already the hard constraint before you add any vision. curious how much slower the loop gets once you're also processing live frames, is video handled on a separate track so it doesn't block the voice turn-taking, or does adding vision to the pipeline push response time up across the board
@galdayan yes exactly its handled separately
@moad_rahali_semlali good to know, that's one less thing to worry about if we ever add vision on our side. nice work
The native voice-to-voice approach instead of a stitched STT, LLM, TTS pipeline is what caught my eye. I'm building a voice AI that phones older adults every day, and the hardest part has been how the agent handles slow, pause-heavy speech and background noise like a TV. Have you tested Eclatira with elderly or hesitant speakers, and how does the turn-taking behave when someone takes a long pause mid-sentence? Would love your thoughts.
@igorgurovich Thanks, and what you're building matters! Yes, we've tested with elderly and hesitant speakers. Because Eclatira is speech-to-speech, the agent hears the rhythm of speech, so it waits through a mid-sentence pause instead of cutting in. It also stays focused on the speaker when there's background noise like a TV. The best proof is to try it with your own use case. Start free at app.eclatira.com