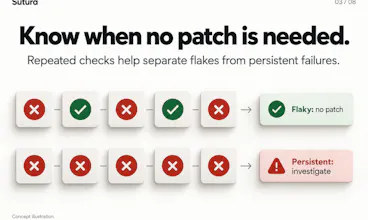
AI agents make CI pass, but a green check does not prove the failure was fixed. Sutura is a GitHub Action and CLI that reproduces the failure in an isolated sandbox, separates flakes from real failures, searches bounded repairs, rejects green-wash (deleted tests, weakened assertions, relaxed config), then puts the winner through an adversarial audit by NVIDIA Nemotron with GPT-6 Astra and TypeSafe Jev as veto-only second opinions. It opens an evidence-backed PR for a human. Never auto-merges.
What became possible in your product with Astra that was not practical before?
Maker
An independent second auditor on every CI repair. Sutura's runtime model is NVIDIA Nemotron; before Astra, the adversarial audit that decides whether a patch really fixed the failure or just made the badge green had a single voice, so a wrong approval had nothing to catch it. Astra now re-runs the same audit question from a different provider and can only veto, never approve, so two independent models must agree before a repair reaches a human. That veto-only shape is what made a second opinion safe to ship: it cannot widen acceptance, only narrow it. It runs live on the public demo today, and every result shows Astra's row next to Nemotron's. Astra was also the coding model this project started with, which is why it was the natural first choice for the audit.
Report
Maker
📌
Hi Product Hunt, Juan here. A few honest notes before you click around.
What runs where. The repair model is NVIDIA Nemotron on Nebius Token Factory, which is the hackathon this was built for. GPT-6 Astra sits in the audit gate as a second opinion: it re-runs the same adversarial question and can only reject a repair, never approve one. A third voice, TypeSafe's Jev, answers the same question as a typed choice with a calibrated probability and confidence, and it can only veto too. All three are visible as rows in every result.
What the Case Lab is. Five fixed cases you can read right now, each with a deterministic replay. Live runs against the public demo repository are capped at 4 per hour and 24 per day; when the cap is hit you still get the recorded result. Today's live smoke result, with all three audit voices on the record: https://sutura-case-lab.vercel.a...
What the numbers are. The v0.3.1 release benchmark ran all 51 Placebo cases on the release commit: zero false approvals, 17 of 19 green-wash traps refused, 10 of 18 repairable failures fixed, 10 of 10 flaky cases correctly left unpatched, USD 3.77 total. Two provider infrastructure stops happened during the run and are disclosed. Evidence files and every workflow URL: https://github.com/juan294/sutur...
What the GPT-6 Astra Challenge was like. Astra was the coding model this project started with, and that is why it ended up inside the product too: it is now the second auditor on every repair, wired in this week and running live on the public demo. Its job is to disagree with Nemotron when Nemotron is wrong, and the evidence shows when it does. Built with Astra, and running Astra.
Ask me anything about the verification gates, the benchmark, or why it refuses to auto-merge.