
akta.pro
Private company data and signals API for the agent economy
691 followers
Private company data and signals API for the agent economy
691 followers
Private company data with 4x the depth and 2x the coverage of PitchBook, plus 100+ event signals and news across companies, industries, and topics. Source and diligence deals or make outreach lists and trigger outbound. Built for financial services and GTM teams, pay-as-you-go.




Hey Product Hunt,
Sid here, co-founder at akta.pro. Private company data and signals API for agents, priced by consumption.
We were building AI agents for private markets and kept hitting the same two dead ends.
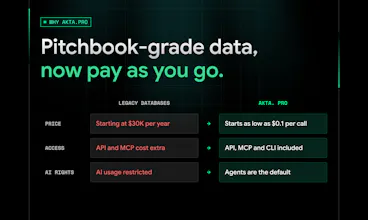
Legacy databases have company data, but they gate it behind a UI, charge by seat, carry no signal layer.
Search APIs return what ranks on SEO. Your agent burns tokens reading 100s of pages to find one event.
akta.pro gives an agent both sides, already structured.
Company data: 20M+ companies with 70+ fields, i.e., 2x coverage of PitchBook, 4x depth of ZoomInfo/Apollo.
Fundamentals: firmographics, management, funding history, investors, revenue and financial estimates.
The fields most databases skip: competitive moat, gtm motion, business model, tech stack, AI maturity.
News and signals: monitor a company, a sector, or a topic in plain language.
Feeds are de-duplicated, matched to the right company, and scored for impact and sentiment.
Tagged across 100+ event types like funding round, exec change, expansion etc., that work as triggers.
Alternative signals tied to the same company ID: headcount trends, web traffic, jobs, social posts, reviews.
On cost, company data runs 5x cheaper than legacy databases like PitchBook. News runs 10x cheaper than putting the same work through Claude or Parallel search APIs, where retrieval comes out of your token spend.
Used today by AI builders shipping agents, GTM teams triggering outbound, and investors screening startups.
Works as an API, over MCP, or CLI.
Try for free. Code PH50 gets you 50 credits: playground.akta.pro/signup/?coupon_code=PH50
If you have evaluated legacy databases, news or search API providers, or GTM intent data, I am happy to do a specific comparison in the comments.
Here all day, and the critical feedback is the useful kind.
@siddhant_masson you mentioned dropping 80% of noise before a response. how are you handling entity resolution upstream to match messy news feeds to the right 20M+ company IDs without blowing up latency?
@mohsinproduct Resolution isn't in the query path at all; tagging happens at capture.
At ingestion, we first use fast candidate-generation and filtering layers—names, aliases, domains, locations, industry/context signals, and our company graph to reduce 20M+ entities to a very small candidate set. Only then do semantic NLP and our in-house resolution models score and disambiguate those candidates. Confidence thresholds determine whether we accept the match or run additional resolution passes. The core algorithm is built in-house and patent pending.
This keeps resolution latency manageable even at feed scale. More importantly, resolution happens at capture, not in the query path. By request time, each article is already mapped to a company ID, so serving is essentially a lookup against a pre-resolved index.
That upstream resolution is also what lets us confidently remove ~80% of irrelevant feed noise. Our recent benchmarks show 93%+ entity-mapping accuracy, ahead of frontier reasoning models on the same task: akta.pro/benchmarks
@mohsinproduct Building on Sid's answer from the implementation side — the latency story comes down to what scales with corpus size and what doesn't. Candidate generation is an index lookup (roughly log-time / sublinear against 20M+), so growing the corpus barely moves that step. The expensive part — semantic disambiguation — only ever runs on the small fixed-size candidate set that lookup returns, never against the full index. So end-to-end resolution time stays effectively flat as we add companies: you're adding rows to the index, not adding work per query.
@siddhant_masson Many congratulations Siddhant, Shiv, Neeraj and team! 😊
When I first met Neeraj discussing the challenges of building AI agents for private-market research. What stood out immediately was how clearly they understood the gap: traditional databases lock valuable company data behind expensive interfaces, while search APIs often return too much noise and consume excessive tokens.
Akta pro brings both sides together through a structured API: deep private-company data across 20M+ companies, enriched with 100+ real-time signals covering funding, hiring, leadership changes, partnerships, expansion, and more.
I’m endorsing it because the team has focused on the details that matter: clean entity resolution, deduplicated data, relevant signals, and consumption-based pricing. It makes private-company research faster, more intelligent, and far more useful for building automated workflows.
It’s built for AI agents, investors, and GTM teams that need actionable intelligence. Definitely worth checking out if you’re working in AI, financial research, or B2B growth. :)
@rohanrecommends thanks Rohan. Its the entity resolution for private company that took us almost 1.5 years to crack (now patent pending). Getting that right changes the game.
@siddhant_masson congrats on the launch🙌 one question where do you pull the headcount trend data from? linkedin/github or aggregated payroll data?
@priya_kushwaha1 We get this from LinkedIn and few aggregated data sources
@rukhsar_amjad Thanks! Pay-as-you-go is the default.
You top up a balance and spend credits per call, no monthly commitment, no seats, so cost scales purely with consumption. MCP and CLI access are included from this tier rather than gated behind an enterprise plan, so you can wire it into Claude, Cursor or your own agent from day one.
We also have Subscription and Enterprise tiers depending on usage and rate limit requirements, custom schemas, bulk export, etc.
Full comparison at akta.pro/pricing
How do you handle companies with very limited public information?
@nuseir_yassin1 for such instances we rely on alternative data such as social media, blogs, podcasts etc. if there is limited information the company itself. We leverage a smart validation logic - if company has very limited public data, not all parameters are populated - only the one's which can be backed by sufficient data are populated while others are left out. Prioritizing accuracy and fidelity yet retaining good fill rates.
How granular are the sentiment and impact scores? Can developers access the underlying scoring fields through the API??
@zerotox yes, numeric scores on a scale of 0 to 1. Raw scores are available in the api response for developers to use.
@zerotox Adding to Sid's point, Both come back as continuous 0–1 floats in the raw response, not bucketed labels, so you set your own thresholds instead of inheriting ours. Impact and sentiment are scored separately — a layoff is high-impact and negative, a small partnership low-impact and positive — so they're pulled apart rather than collapsed into one good/bad number. Story centrality is a third field: whether the company is the subject or just mentioned, which is usually what you actually want to filter triggers on. All exposed, all filterable at query.
Cool. Can you set up notifications when a specific signal is triggered? And can you create custom signals?
@natalia_iankovych Custom signals, yes. Filtering happens at the query rather than from a preset list of alert types, so you define what counts as a signal. Filter across a 70+ category news taxonomy, plus IAB and IPTC codes, scoped to whatever set of companies you're tracking. So a watchlist filtered to funding and leadership changes, and a separate one for competitors filtered to product launches, are just two queries against the same endpoint.
On notifications, webhooks for signal alerts are on the roadmap. Until then you poll the news API on whatever frequency suits you, and credits are only charged on news actually returned, so empty polls cost nothing and you can run a tight loop without paying for quiet periods.
@saswat_nanda2 I have a slightly different use case: I have several thousand potential clients and around 10 signals that should trigger me to reach out to them with an offer. I need to track these signals daily/weekly and receive an email notification when one of them appears. Is something like this possible?
@natalia_iankovych Yes, this is exactly what the webhooks I referred above can solve. You define a set of companies, the signals you care about, and a frequency, then get a webhook plus email notification when any of them fires. Several thousand companies against 10 signal types is well within what it's built for.
Until that ships, a scheduled poll on the news API gets you the same outcome. The filtering and company scoping is already there, and credits are only charged on news actually returned, so a daily run over a quiet list costs almost nothing.
For the email step, n8n or Zapier will do it without any code, both can run the API call on a schedule and route hits into an email.
Happy to chat over a quick call. Also, will give you a heads-up once webhooks are live.
This is great. Congrats, Siddhant and team.
Since those are synthesized rather than reported data, would I be able to see what a given moat call was drawn from, or do I take the field as given?
@tmaleh_ Fair question, and and the short answer is you can see what it was drawn from.
Moat isn't returned as a single verdict. competitive_moat comes back as an array of typed entries, each tagged to a category, distribution advantage, switching costs, network effects, cost advantage, ecosystem lock-in, data advantage, with the specific reasoning attached to each. So you can see which dimensions are actually carrying the call and which are thin.
It also sits inside a broader company_assessment section, alongside strengths, weaknesses, key risks and key highlights. Those are fully source-traced, each entry carrying links to what it was drawn from, and the moat read is the analysis layered on that same evidence base. So the reasoning is inspectable by looking at what it was built from.
We built source traceability into the architecture itself. Any output meant for diligence has to be something you can audit back to what produced it.
As a developer, having this available through API, MCP, and CLI makes the product flexible and interesting to use. Congrats on the launch!
@roopreddy Thanks Roop. That was the intent,. We wanted the choice of surface to be about how you work rather than a tradeoff, so API, MCP and CLI all return the same shapes.