

Our AI kept overruling the corrections users made
W
e let people correct us. Mark a sender as important. Fix a classification we got wrong. Tell us something we flagged as revenue isn't actually revenue.
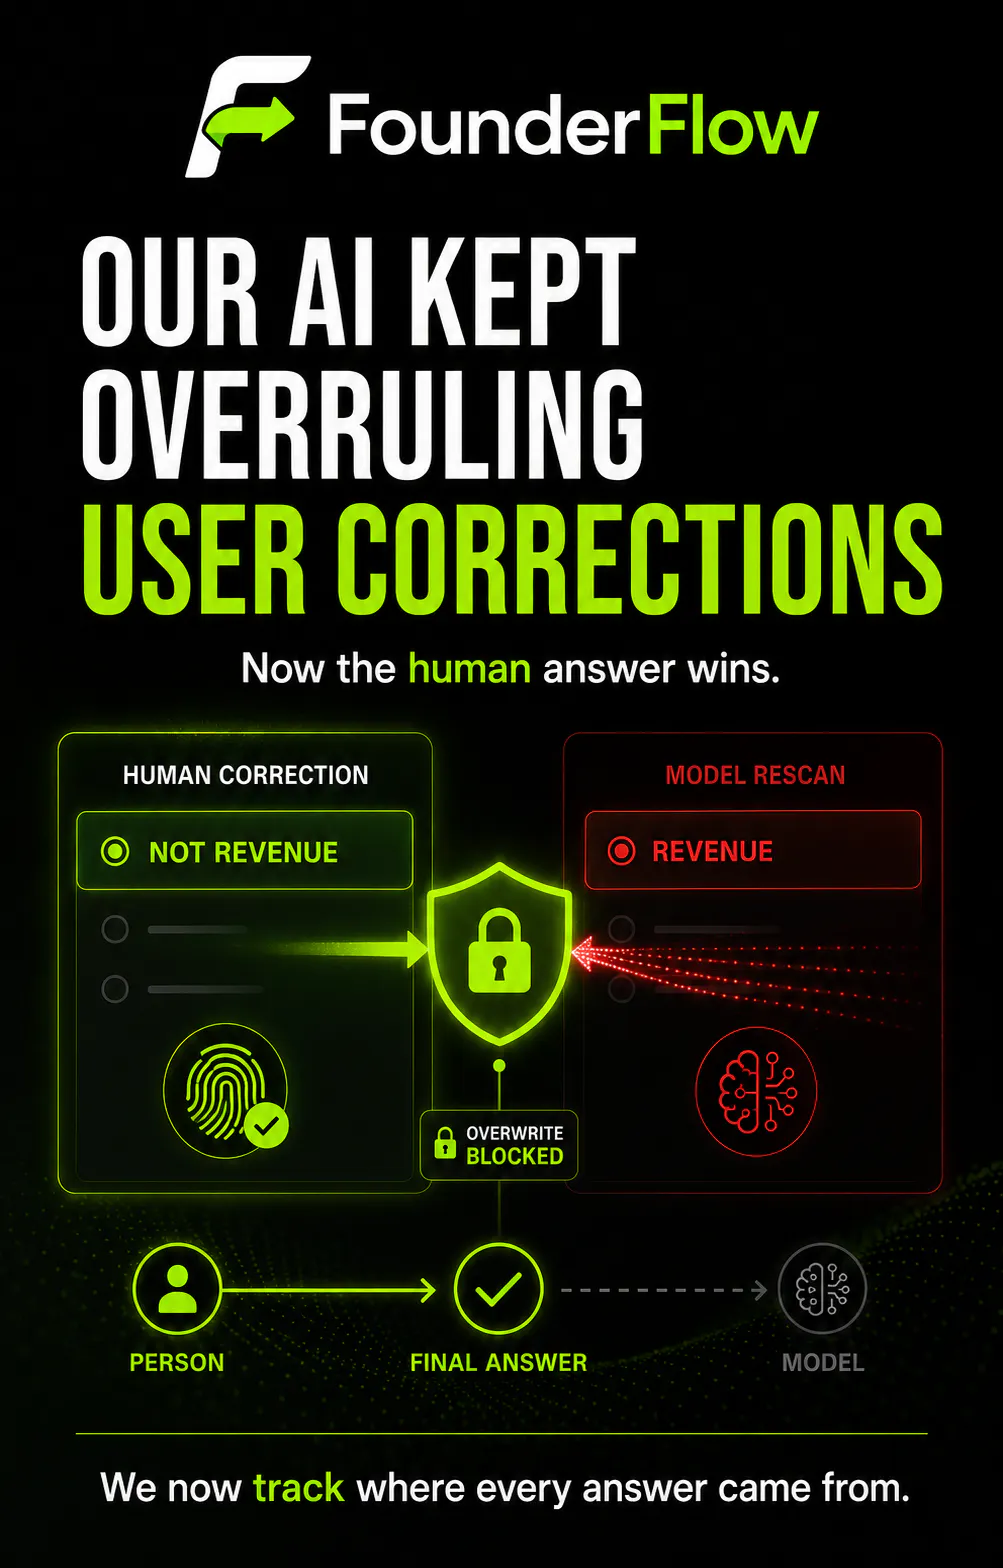
Then a background job would rescan that same email later and quietly put its own answer back.
So someone tells the system "this isn't revenue," and the next day there it is again. From their side that isn't a bug, it's a personality. Being wrong once is forgivable. Being wrong again after they fixed it means the thing doesn't listen.
We'd already caught one process doing this and patched it. Went looking anyway and found a second writer sitting in the main classification flow. That's the part that still bothers me — nobody reported it. We just had a whole second thing writing to those fields that nobody had inventoried.
The fix itself is boring. Human answer wins, and we store where each value came from, model or person.
What I keep chewing on is that a system learning from corrections and a system overwriting them look identical from the inside. Same tables, same code path. The only difference is whether anything tracks provenance, and we weren't tracking it because we'd spent all our attention on accuracy and none on who gets the last word.
So for anyone else building on a model — how are you handling this? Do you store where a value came from, or does newest write just win? I don't think we've solved it. We've stopped the bleeding.
Replies