
Weave understands engineering work by combining LLMs and domain-specific machine learning. We tell you how much work is getting done, how good it is and how to optimize your token allocation. Used by startups and the fortune 100 (YC W25).
This is the 3rd launch from Weave Engineering Intelligence. View more

Weave Router 2.0
Launched this week
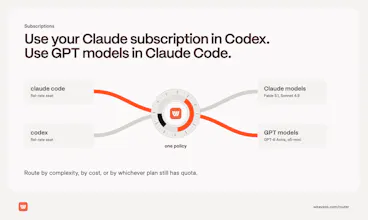
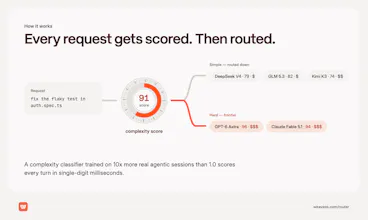
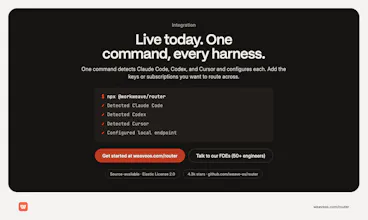
Use Claude models in Codex and GPT models in Claude Code on your existing plans, routed to whichever has quota left. Weave Router 2.0 routes each coding agent request to the cheapest model that can get it right. On Terminal-Bench 4.0 and SWE-Atlas it matches GPT-6 Astra at half the cost, 2x faster. Powered by a new classifier that scores task complexity and cache-aware switching that only moves when savings beat the rebuild cost.




Free Options
Launch Team / Built With


using weave is a quite great experience for me and my team, it save a lot of our time. my support is with you best of luck with the launch.
Weave Engineering Intelligence
@donald_leo amazing to hear, thank you :)
Very awesome guys - especially now that the 20x plan in codex is temporarily disabled 😵😵😵
Weave Engineering Intelligence
@ilyatkachov ahaha 100%
Kick
Congrats on the launch, guys!
Weave Engineering Intelligence
@andrew_roth2 thanks!
Congrats on the launch! 🙌 🙌 was literally just weighting a local model to cut agent costs, and this is the smarter take.
quick question - when it routes down and gets it wrong, does it catch it med-task and bump back up, or do i only find out after a cheaper model quietly shipped a worse answer? and, is the routing personalized at all, does it learn from my own history or feedback over time, or is it one global classifier for everyone?
neat idea either way 😃
Love this. Once you're running more than one coding agent, subscription-aware routing stops being a nice-to-have. Excited to try how you balance quality and cost across models.
The cache-aware switching is the detail that makes this feel practical, since a cheaper model is not really cheaper if every switch rebuilds a large context. I also like that the model pool stays configurable.