
Weave understands engineering work by combining LLMs and domain-specific machine learning. We tell you how much work is getting done, how good it is and how to optimize your token allocation. Used by startups and the fortune 100 (YC W25).
This is the 3rd launch from Weave Engineering Intelligence. View more

Weave Router 2.0
Launched this week
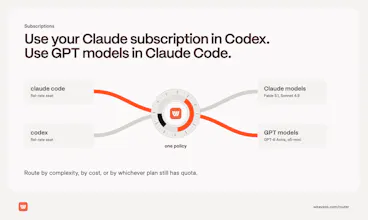
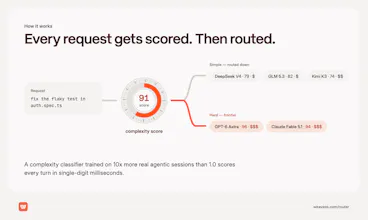
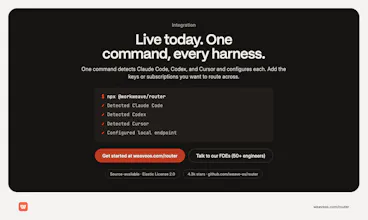
Use Claude models in Codex and GPT models in Claude Code on your existing plans, routed to whichever has quota left. Weave Router 2.0 routes each coding agent request to the cheapest model that can get it right. On Terminal-Bench 4.0 and SWE-Atlas it matches GPT-6 Astra at half the cost, 2x faster. Powered by a new classifier that scores task complexity and cache-aware switching that only moves when savings beat the rebuild cost.




Free Options
Launch Team / Built With


Congrats on the launch! This looks really useful. My Question: Is there a free tier to try it out first?
Weave Engineering Intelligence
Hello everyone! 🎉 I'm thrilled that we've launched Weave Router 2.0! 🚀 Many of you have seen us preparing for the launch, and we've done it! Today is a big day for us, as this launch is actually our first public product release.
We would greatly appreciate your feedback, comments, and reviews. 💬
Also, as a gift to all Product Hunt community members, we are offering a 20% discount on routing through the end of 2026!
using weave allowed our lead engineers to optimize overall workflow speed by sixteen percent.
I have used Weave for my team and it noticeably improved our engineering output.
Weave Engineering Intelligence
@joseph_collins2 love to hear it :)
Does it shows users why a specific model was chosen for each request?
Weave Engineering Intelligence
@ethanc44 we don't have this, but will def add it as a feature request!
I have been using Weave and the experience has been great, especially because it significantly reduces token costs.
Weave Engineering Intelligence
@thomas_jack3 amazing to year that :)