
Throttle
Smart routing for LLM inference, save thousands on API costs
2 followers
Smart routing for LLM inference, save thousands on API costs
2 followers
We built Throttle because teams are bleeding money on LLM inference. Your bill keeps climbing even though you're not using better models. Throttle sits between your code and Claude/OpenAI, automatically routes requests to cheaper models when quality isn't sacrificed, caches intelligently, and batches efficiently. Result: 70% cost cuts, same performance. Built for startups and companies already paying $1000+/month on inference.




Hey Product Hunt 👋
I'm Kushagra. I built Throttle because I kept changing my LLM server's config and could never tell if it actually got cheaper, or if I just measured a quiet minute.
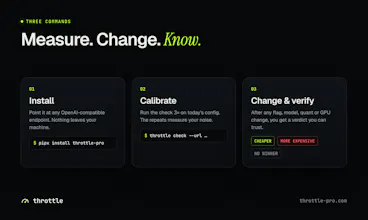
Measure. Change. Know.
- Measure what your model really costs per million tokens, on any OpenAI-compatible endpoint (vLLM, SGLang, Ollama, TGI).
- Change anything: a flag, a quantization, a new GPU.
- Know if it worked: CHEAPER, MORE EXPENSIVE or NO WINNER. It won't call a winner until repeat runs have measured the noise.
How it works:
Throttle runs repeated measurement blocks with 95% confidence intervals, fingerprints your serving config, and compares each run with your history.
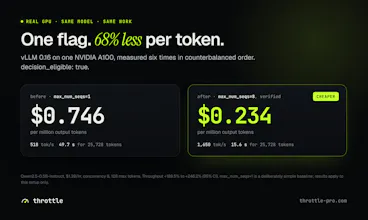
On a real A100, one vLLM flag took cost from $0.746 to $0.234 per million tokens, verified with a six-run counterbalanced protocol.
Open source and local: `pipx install throttle-pro`. Add the GitHub Action and a deploy that costs more fails CI.