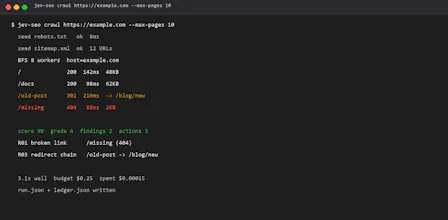
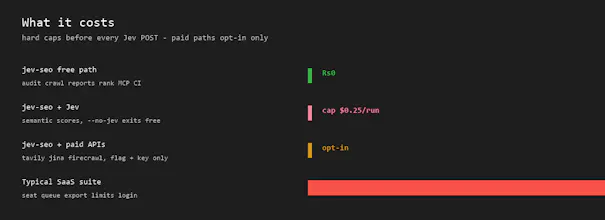
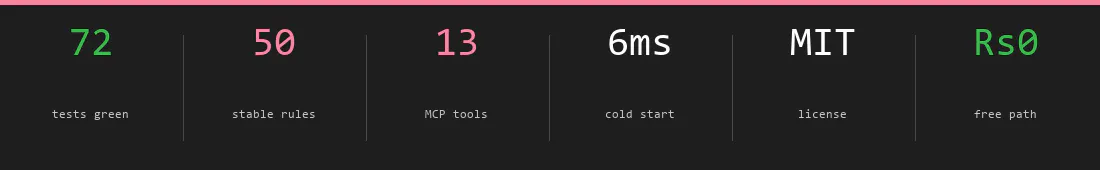
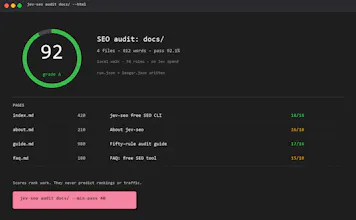
Semrush and Ahrefs cost $130+/month for work that's mostly deterministic: crawling a site, checking meta tags, validating schema, checking what AI crawlers can see. jev-seo does that in a free Rust CLI. No subscription, no paid API keys needed for the core checks (crawl, audit, schema, robots, sitemap). Optional Jev-powered semantic scoring (intent classification, GEO/AI-citation scoring) needs a free API key. Also ships as an MCP server for coding agents. cargo install jev-seo
Hey PH 👋 Built jev-seo because I got tired of the idea that checking your own site's SEO health needs a $130/month subscription.
Crawl your site, audit your docs, validate schema and sitemaps, check what AI crawlers (GPTBot, ClaudeBot, etc) can see, all free, all local, no API key required for any of it. There's an optional layer that uses TypeSafe's Jev model for semantic scoring (search intent, AI-citation likelihood), that part needs a free key, everything else doesn't.
It's also an MCP server, so if you're using Claude Code or another agent, it can call the same tools directly.
Solo project, built out of Patna, India. Would love feedback, especially from anyone doing SEO work who can tell me what's missing.
cargo install jev-seo
For me the missing piece is pages that are supposed to die. I run a job board where a few thousand listings expire every week across 11 languages, and the audits that actually bit us were never meta tags. It was hreflang clusters pointing at a translation we had already noindexed, and closed listings that kept returning 200 with a "this job is closed" block, so they sat in the sitemap as thin pages for weeks. A robots check also happily told us GPTBot was allowed while our homepage only filled in its content after JS, so what the crawler really got was mostly an empty shell. When jev-seo checks what AI crawlers can see, does it fetch the raw HTML or render it, and could it diff the two?



jev-seo
Lancepilot
jev-seo
@priyankamandal thanx
For me the missing piece is pages that are supposed to die. I run a job board where a few thousand listings expire every week across 11 languages, and the audits that actually bit us were never meta tags. It was hreflang clusters pointing at a translation we had already noindexed, and closed listings that kept returning 200 with a "this job is closed" block, so they sat in the sitemap as thin pages for weeks. A robots check also happily told us GPTBot was allowed while our homepage only filled in its content after JS, so what the crawler really got was mostly an empty shell. When jev-seo checks what AI crawlers can see, does it fetch the raw HTML or render it, and could it diff the two?