Reviewers describe Context.dev as a fast, simple web-fetch and enrichment layer that works especially well for AI agents. Users say it turns web content into clean, structured, model-ready data, cutting token waste and avoiding the burden of maintaining scrapers, proxies, and cleanup logic. Founders behind
Migma AI,
Notra, and
Construct Computer cite strong reliability, high concurrency, and responsive support. The main criticisms are thinner docs, some rough edges in brand color extraction, and limited visibility into domain-level compliance changes.




 Firecrawl
Context.dev
Hey folks! Yahia here, founder of Context.dev 👋
If you’ve built a product that needs information from the web, you know how quickly a simple question turns into a whole engineering project.
Find the right pages, scrape them, feed them into a model, get the output into something your code can actually use.
We wanted to make that one API call.
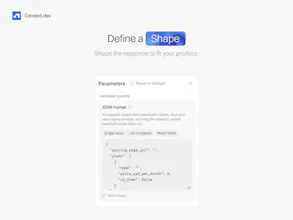
Today we’re launching /answers. Give it a research task and an example of the JSON you want back. It searches the web, reads relevant pages, and returns structured data with source URLs.
Things like:
“Find this company’s pricing plans and what’s included in each.”
“Does this product support self-hosting?”
“Compare these three tools on pricing and integrations.”
You choose the output fields so the answer fits directly into whatever you’re building. There’s a Fast mode for focused lookups and Ultra for deeper research.
Our goal with Context.dev has always been to make it ridiculously easy to get web data into your products and agents. This is a pretty big step toward that.
Extremely stoked to get it into your hands. Throw a real task at it and tell us where it falls short. I’d love the feedback, especially from the grumpy engineers :)
Okibi