
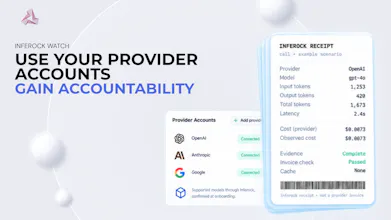
Inferock-bench is a local proxy that sits between your app and OpenAI, Anthropic, Gemini, or OpenRouter shaped calls. It captures per-call token usage, failures, and retries, then generates an independent receipt showing what you were billed and how much you're actually overpaying for.
This is the 2nd launch from Inferock. View more

Inferock
Launching today
Get free signup credits to use all available models on Inferock.
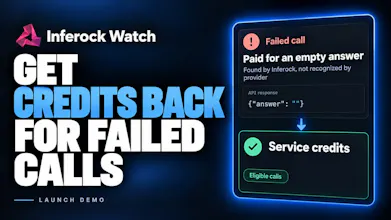
Bring your own keys: run your OpenAI, Claude or Gemini accounts, see where calls fail and what they cost, and get credits back on eligible failed calls.
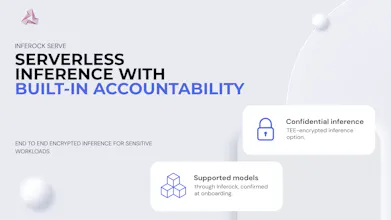
Serverless: pay-per-token LLM inference. Get signup credits to start using.


Free Options
Launch Team / Built With


Dropbox SignSimple, secure eSignatures for the way your team works.
Promoted


Hi Product Hunt community, I’m Bharath, founder of Inferock.
Every team running LLMs in production pays for calls that came back empty, truncated, timed out, or returned broken JSON. You usually find out from a user, and you can’t prove it to anyone.
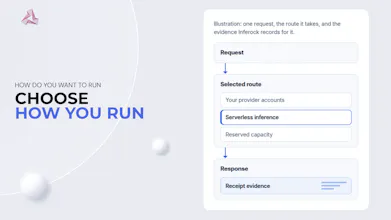
Inferock sits between your app and the provider and measures every call against a published baseline for quality, speed and cost. Each call gets a receipt that Inferock produces itself, so it doesn’t depend on the provider’s word.
Two ways to use it:
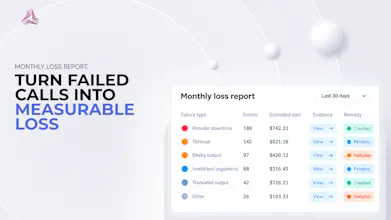
- Inferock Watch: bring your own OpenAI, Anthropic or Gemini keys. Free. You get the receipts and a monthly loss report. Enroll in the credit program and objectively broken calls accrue credits you can spend on Serve.
- Inferock Serve: serverless, pay-per-token inference through us. This is where your credits get spent.
How credits work: credits are non-cash, expire after 12 months, and are capped at $1,000 in the wallet and $1,000 applied per month. They cover verified, billed, unrecovered objective failures: downtime and timeouts, empty or truncated output, invalid structured output, billing and cache anomalies.
Tell us what the receipt should show that it doesn’t yet.
I love that it sits as a local proxy rather than requiring us to pipe sensitive request data tthrough a third party cloud dashboard.
I have been looking for an independent auditor for LLM tokens because developer dashboards often feel a bit opaque when it comes to exact token counts.