
Weave understands engineering work by combining LLMs and domain-specific machine learning. We tell you how much work is getting done, how good it is and how to optimize your token allocation. Used by startups and the fortune 100 (YC W25).
This is the 3rd launch from Weave Engineering Intelligence. View more

Weave Router 2.0
Launched this week
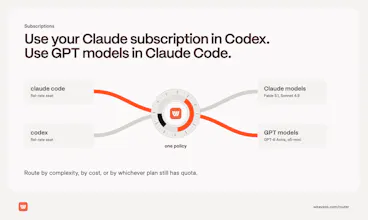
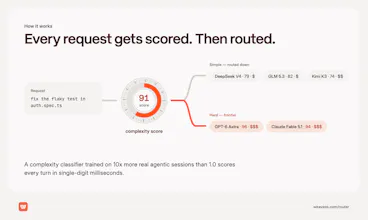
Use Claude models in Codex and GPT models in Claude Code on your existing plans, routed to whichever has quota left. Weave Router 2.0 routes each coding agent request to the cheapest model that can get it right. On Terminal-Bench 4.0 and SWE-Atlas it matches GPT-6 Astra at half the cost, 2x faster. Powered by a new classifier that scores task complexity and cache-aware switching that only moves when savings beat the rebuild cost.




Free Options
Launch Team / Built With


Given that this routing is done via quota across the providers, what will happen if there is a case whereby the quotas for Claude and GPT are depleted at the same time?
Additionally, Congratualtions @adchurch @adambcohen & team @Weave Engineering Intelligence 🚀✌️
Weave Engineering Intelligence
@aymi_malik Hey Muhammad, great question. In this case we still try to route to the best model for the job, whether that be an open source model or one of the Anthropic/OpenAI models at API pricing.
Congrats on the launch. I'm interested to know that when a cheaper model gets a turn slightly wrong, does the router notice and escalate on the next turn, or does the agent carry the mistake forward?
Weave Engineering Intelligence
@joy_gu yes it does! it's aware that if it's running and not working as effectively as possible it will escalate it to a more intelligent model.
Does it support custom cost caps per project?
Weave Engineering Intelligence
@advin_jadis We haven't built this feature yet but that's a great idea!
Do you have a VS Code extension coming?
Weave Engineering Intelligence
@henryevans11 yes!
The cheapest model that can get it right approach is really interesting How does Weave decide which model is best for each coding task?
Weave Engineering Intelligence
@shivam_kushwaha16 We trained a model on an extremely large dataset that we gathered from customer agent traces as well as model rollouts and continuously improve via RLHF!
How does Weave decide which model is capable enough for s specific coding task?
Weave Engineering Intelligence
@maxwellbarnes00 We trained a model on an extremely large dataset of labeled prompts and continuously improve via RL!