Launching today

Redactic
GDPR document redaction for AI, processed in the EU
2 followers
GDPR document redaction for AI, processed in the EU
2 followers
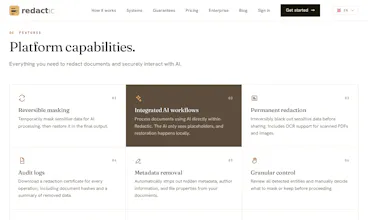
Redactic finds personal data in PDF, Word, Excel, images and scanned documents. Mask it with reversible placeholders before using AI and get the real values restored in your browser, or black it out permanently on the page before sharing. National IDs are validated by check digit. Files are processed in the EU, never stored and never used to train models.




Payment Required
Launch Team

ClarifyThe full-stack AI CRM for modern GTM teams
Promoted
Hi Product Hunt, I'm Luca and I built Redactic.
Redactic is for professionals in Europe who work with personal data every day, such as lawyers, HR and payroll offices and accountants, and who want to use AI on their documents without handing that data to a model provider.
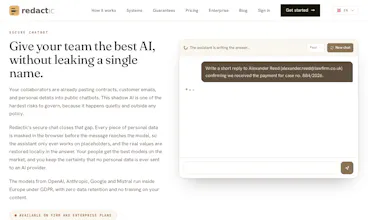
It does two things. It can mask the personal data in a PDF, Word or Excel file or a scan, so the AI only ever sees placeholders and the real values come back in your browser when the answer arrives. Or it can black the data out on the page when the file has to be shared with someone else.
Building it for European users shaped a few decisions. Processing runs on EU infrastructure and documents are not kept after the job. National identifiers are recognised by their own format and check digit, for example the Italian Codice Fiscale, the German Steuer-IdNr, the French NIR and the Spanish DNI, because generic detectors tend to miss them. We sign the DPA as processor when you subscribe, so the paperwork is already there for your compliance team.
If your documents use national ID formats we don't handle yet, tell me which country and I'll put it at the top of the list.