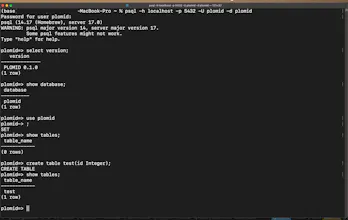
PLOMID - (Platform for Modern Intelligence and Data) is a unified data infrastructure platform that brings multiple data models and workloads toward a common underlying data layer. PLOMID provides SQL and JSON capabilities, with vector, graph, distributed, multi-region and AI-native capabilities on the roadmap. The goal is to reduce fragmentation across data layers while giving developers a consistent foundation for modern applications.
We’re building PLOMID around a simple question: what if modern applications didn’t have to keep stitching together separate data systems for different workloads?
PLOMID is designed as a unified data infrastructure layer for multiple data models and workloads.
The current implementation includes SQL and JSON, with vector, graph, distributed and multi-region capabilities being developed next.
This is an early stage of a much larger engineering project, and I’m launching it here to get feedback from developers, database engineers, infrastructure builders, and anyone working with increasingly fragmented data stacks.
Would love to hear what you think about the architecture, the problem, and where you think we should take it next.