Launching today

Inception Mercury Voice
A real-time reasoning model for voice agents
1 follower
A real-time reasoning model for voice agents
1 follower
Mercury Voice is Inception's diffusion LLM built to power voice agents. It reasons, calls tools, and follows long system prompts while returning its first answer token in 320 ms (median), 5.9x faster than GPT-6 Luna (no reasoning). It beats Gemma 4 31B and GLM-5.3-Flash on agentic and voice benchmarks, at about $0.009 per minute of conversation. OpenAI API compatible, so it works with LiveKit, Pipecat, Vapi and Retell.


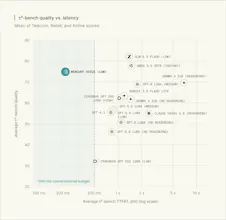
Mercury Voice is Inception's diffusion LLM (dLLM) tuned to power voice agents, now generally available for enterprise customers.
Problem: On a phone call, the agent has to respond within about 500 ms of the caller finishing, or the pause feels awkward. Smart reasoning models are too slow for that, so most voice builders default to fast non-reasoning models like GPT-4.1 or Gemma 4 31B (no reasoning) that can only follow basic instructions.
Solution: A reasoning model tuned for real-time conversation. It reasons, calls tools, and follows long system prompts while staying fast enough that the model isn't the bottleneck.
What makes it different: It doesn't make you pick between smart and fast. Median time to first answer token is 320 ms (p95: 750 ms), 5.9x faster than GPT-6 Luna (no reasoning). It also beats Gemma 4 31B, GPT-6 Luna, GLM-5.3-Flash and Qwen3.5-397B on a composite of agentic and conversational benchmarks (τ³-bench, IFBench, BFCL v4). Tail latency matters too, since a p95 of four seconds means roughly one turn in twenty fails.
Key features:
320 ms median time to first answer token, 750 ms at p95
3 reasoning effort settings (low, medium, high)
128K context with up to 50K output tokens
About $0.009 per minute of conversation, roughly 5x cheaper than GPT-4.1
$0.40 / $1.50 per million input / output tokens, currently 50% off at launch ($0.20 / $0.75)
OpenAI API compatible, drops into LiveKit, Pipecat, Vapi, Retell or your own stack
Who it's for: Teams building voice agents for customer service, ordering, or collections. Already in production at Audivi AI (drive-thru ordering), Altur (payment plan calls for financial institutions), and OpenCall (AI phone agents, median latency close to 170 ms).
Try it: Available to enterprise customers via the Inception API, reach out at sales@inceptionlabs.ai.