
Claude Opus 4.7
Claude’s most capable model for reasoning and agentic coding
5.0•10 reviews•1K followers
Claude’s most capable model for reasoning and agentic coding
5.0•10 reviews•1K followers
Claude Opus 4.7 is Anthropic’s most advanced generally available AI model, built for complex reasoning and agentic coding. It handles long-running tasks, follows instructions precisely, verifies outputs, and delivers high-quality results across coding, research, and workflows.




Free Options
Launch Team

MotifCalm, tough or hype: an AI coach for your wearable data
Promoted

Anthropic released Opus 4.7 today. Same pricing as 4.6 ($5/$25 per million tokens), available across API, Bedrock, Vertex AI, and Microsoft Foundry.
What changed vs 4.6:
Coding. Biggest gains on long-horizon software engineering tasks. Model now verifies its own outputs before reporting back.
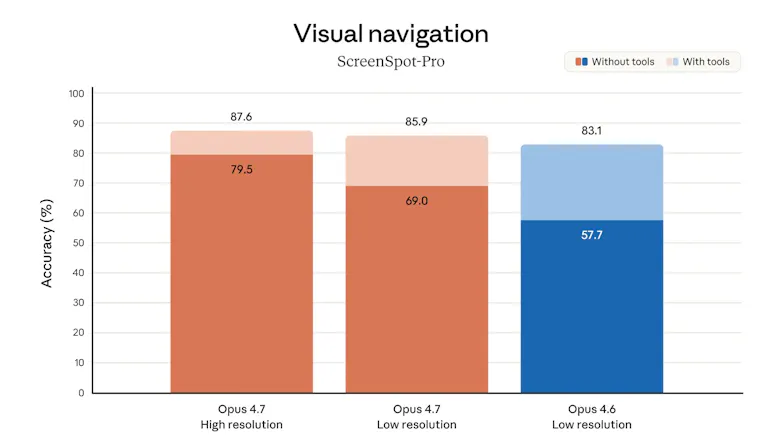
Vision. Accepts images up to 2,576px (~3.75MP)- over 3x more than any prior Claude. Key unlock for computer-use agents and diagram extraction.
Instruction following. Now interprets literally. Anthropic warns: prompts tuned for 4.6 may break — re-tuning needed.
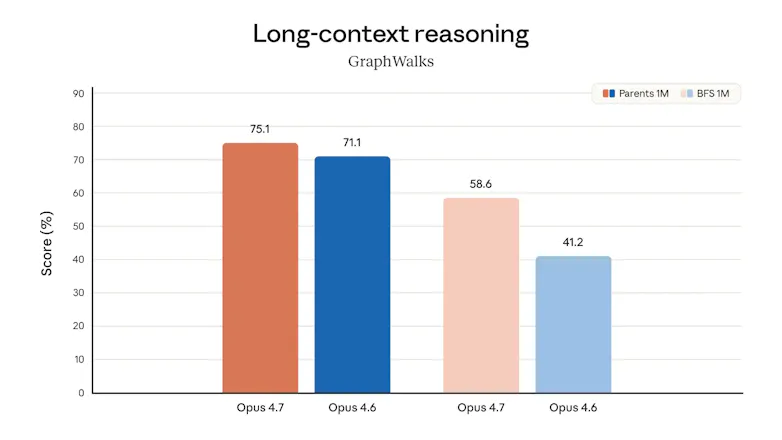
Memory. Better at file system-based memory across long multi-session work.
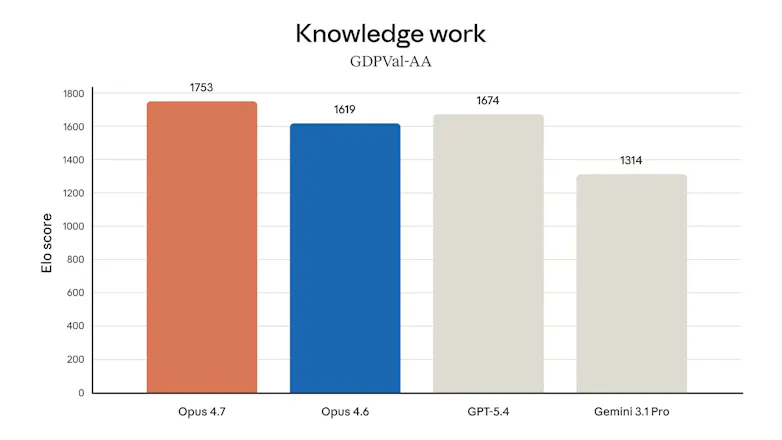
Real-world knowledge work. State-of-the-art on Finance Agent eval and GDPval-AA.
New features:
xhigh effort level between high and max - finer control over reasoning vs. latency. Claude Code default is now xhigh for all plans.
Task budgets in public beta on the API.
/ultrareview in Claude Code - dedicated review session flagging bugs and design issues. Three free for Pro and Max users.
Auto mode extended to Claude Code Max users.
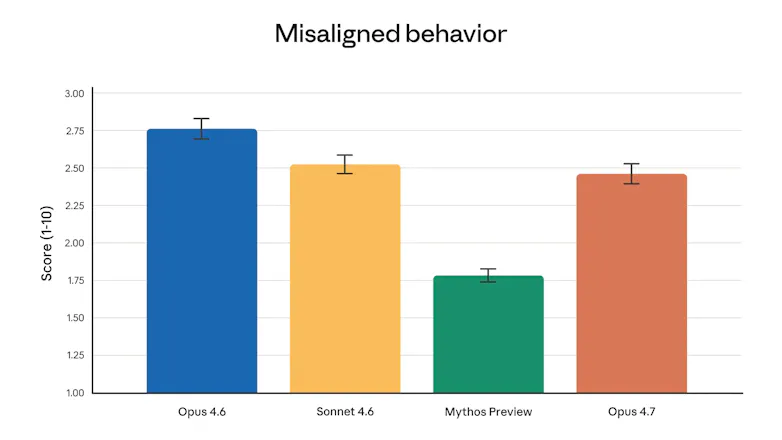
Honest caveats: New tokenizer → same input maps to up to 1.35x more tokens. Opus 4.7 thinks more at higher effort levels, especially on later agentic turns. Safety profile is roughly similar to 4.6 — improvement on honesty and prompt injection resistance, modestly weaker on harm-reduction advice for controlled substances. Still less capable than Claude Mythos Preview, which remains on limited release.
Bottom line: Meaningful upgrade in the three places that matter most- agentic coding reliability, vision for computer-use agents, and knowledge work benchmarks. Solid iteration, obviously shy of Mythos.
I believe they have started using Opus 4.7 for Claude Design too which is also one of their recent launches. I wonder if Opus 4.7 is so good, how good will Claude Mythos be?