
Vidu is the world’s first multimodal model to support Multi-Entity Consistency! Vidu can seamlessly integrate people, objects, and environments to generate stunning videos, overturning traditional single-point fine-tuning methods like Lora. This release marks a leap in unified understanding and generation, setting a new standard in multimodal AI.
This is the 3rd launch from Vidu AI Video Generator. View more

Vidu Q4
Launching today
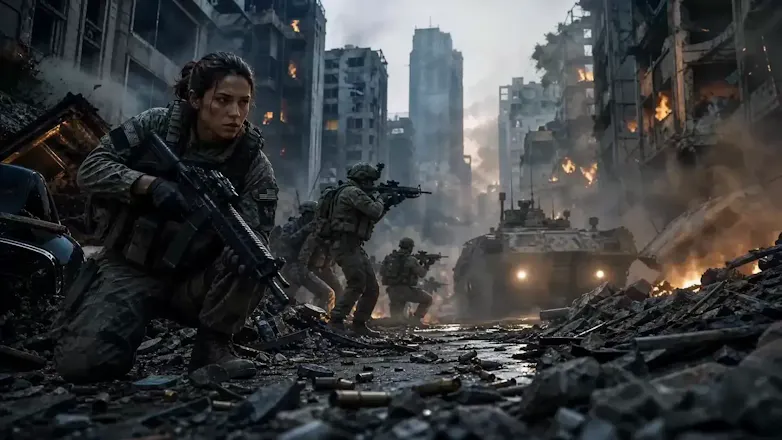
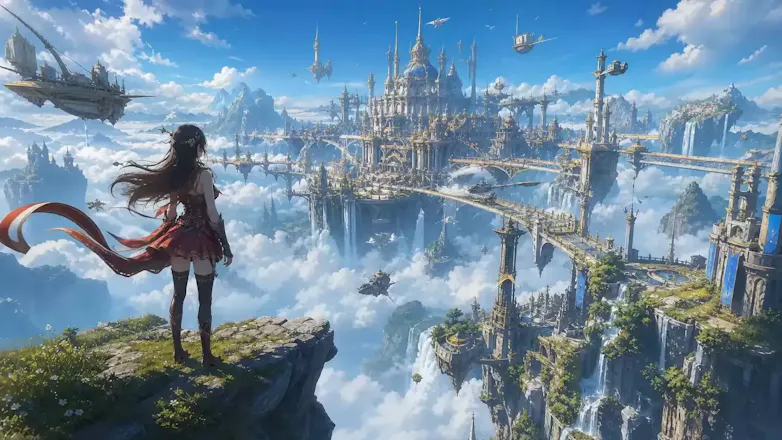
Explore Vidu Q4, an AI video generation model with native audio, faster motion quality, and stronger prompt control for creative work.



Free Options
Launch Team

EneyProactive AI for Mac. Free test, 20,000 credits.
Promoted


Hi everyone!
Vidu Q4 is here in preview. Reference-to-Video now takes up to 15 images and 3 voice clips.
Say you're making a short scene with two people. You can bring in different views of both characters, their clothes, the room, a few props, and samples of their voices. Then describe the dialogue and camera moves, and let Q4 put the scene together.
Q3 already supported native audio and multi-shot video. Q4 raises the image reference limit from 7 to 15, adds 2K and 4K output, and puts more emphasis on facial expressions, body movement, and camera cuts. Clips still go up to 16 seconds.
Q4 Preview also landed near the top of AA's image-to-video leaderboard!