Launching today

Synthetic Webcam Scene Dataset
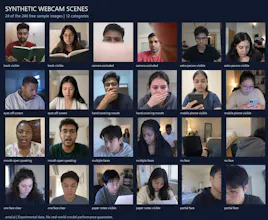
17,280 synthetic webcam images for computer vision
3 followers
17,280 synthetic webcam images for computer vision
3 followers
17,280 text-generated webcam images in 12 categories, with prompts, provenance and companion source code. Built for computer-vision experiments exploring human proctor assistance. USD 99 once, with a free 240-image sample. No trained model included.

Antal.Ai Person Pixelizer (FREE)
Hi Product Hunt, I’m Antal, an independent computer-vision engineer.
I’m sharing a dataset of 17,280 synthetic webcam images, organized into 12 scene categories. The full collection costs USD 99 as a one-time purchase, and you can inspect a free 240-image sample before deciding.
The categories cover face visibility, additional people, phones, books, paper notes, camera obstruction and other webcam observations. I generated the images entirely from text prompts; I did not upload photographs of real people as generation inputs.
The goal behind the project was to assist a live human proctor, not to automatically decide who was cheating. Flagging potentially suspicious events could help one proctor supervise more participants and focus on the streams needing review. The human would assess the context and make any decision about misconduct. More cost-effective supervision was a design goal, not a measured outcome of this experiment.
What you get:
- 17,280 RGB JPEG crops in category folders.
- 720 original PNG contact sheets containing those same scenes.
- 12 generation prompts, source-to-crop records and checksums.
- Companion code for extraction, training, ONNX export and C++/OpenCV integration.
The value is the collection already generated, extracted and organized. Based on my own workflow, I estimate that generating this volume again would cost slightly more than USD 99, before the time needed to crop, organize and review it.
A practical note: these are experimental data, and the labels reflect the intended generation categories rather than exhaustive manual annotation. My classifier did not achieve satisfactory real-world accuracy. The supplied train/validation split shares source sheets, so use the provenance records to create source-separated evaluation splits. No trained model, support or performance guarantee is included.
Dataset, sample and purchase details:
https://www.antal.ai/projects/sy...
The case study documents the workflow and its limitations:
https://www.antal.ai/blog/synthe...
Which scene category or evaluation detail would matter most for your own experiments? I’d appreciate feedback on the sample and dataset documentation.