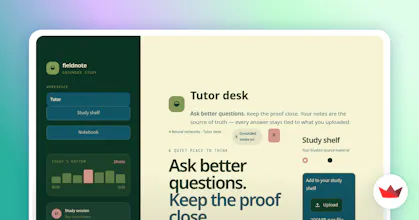
The RAG-based Tutoring Chatbot is made using Python, LangChain and FAISS. The system retrieves relevant context from a knowledge base before generating answers with Gemini Flash, grounding responses instead of relying on the model's raw knowledge.I evaluated it with the RAGAS framework, achieving ~0.87 faithfulness and ~0.83 answer relevancy, and deployed it live on Streamlit Community Cloud.I built this project from scratch with no prior coding experience, learning Git and GitHub along the way.
This started as my NTCC project in college, but what really pulled me in was wanting to solve a real problem with LLMs — they can hallucinate or give outdated answers, which is risky for academic content that needs to be accurate and traceable. So I set out to build a tutoring chatbot that retrieves relevant context from a knowledge base before generating a response, grounding answers instead of just guessing plausibly. My approach evolved a lot along the way: I started with local sentence-transformer embeddings but hit RAM limits deploying on Streamlit Community Cloud's free tier, so I switched to the Gemini embeddings API; I had to pin my Python version after dependency conflicts, and debug a Gemini model deprecation mid-project. I also went from zero coding background to learning Git and GitHub through the browser UI, and eventually evaluating my system's output quality with RAGAS instead of just assuming it worked — which changed how I thought about "done."