
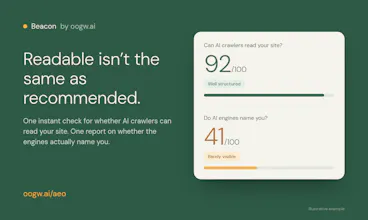
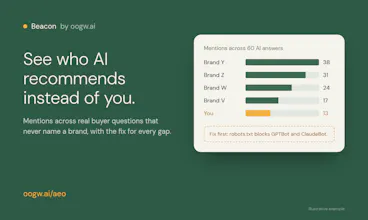
Most AEO tools score your HTML and call it AI visibility. Beacon actually asks the engines. We put unbranded buyer questions about your category to ChatGPT and Gemini (Claude on the full audit), then show how often you're named, who gets named instead, and which sources the engines trust. Two separate answers: can AI crawlers read your site (instant, no sign-up), and do the engines recommend you? Every gap comes with the fix.



@saiedreem How does Beacon handle different answers from ChatGPT and Gemini ?
@dipanshu_kushwaha5 good question.
Beacon doesn't try to reconcile ChatGPT and Gemini etc.
It treats the disagreement between LLMs as a finding.
Each engine runs independently. ChatGPT goes through the Responses API on Bing-backed search. Gemini goes through generateContent with Google Search grounding. Claude on BRAVE.
Each gets the same brand-free buyer questions, and each answer is scored separately for whether the brand is named, where it ranks, which competitors show up, and how it's framed. Nothing is cross-checked or averaged at the answer level.
The spread is shown, not smoothed. The report gives per-engine counts (named in X of N questions on ChatGPT, Y of N on Gemini) next to the combined pillar scores.
The composite is built on top of that. Brand Visibility, Share of Voice, Average Position and Sentiment each pool results across engines. Then the five pillars combine by weighted average into the headline score.
Divergence is explainable, which makes it useful. The two engines pull from different indexes, and ChatGPT re-ranks Bing results heavily. So "Gemini names you, ChatGPT doesn't" usually points to a Bing indexing or citation-source gap, which is a concrete fix.
@saiedreem Congratulations on the launch! Beacon looks like a really useful tool for understanding how AI engines actually discover and recommend your brand.
Check your AEO readability now. https://oogw.ai/aeo
Congrats on the launch, Reem. The gap between the score and what the engines actually do matches what we saw from the other side: when we checked the server logs of our own WordPress sites, GPTBot, ClaudeBot and PerplexityBot were fetching pages every day, often hitting 404s nobody knew about, and no audit score showed it. Do you plan to let a site connect its own crawler logs, so a missing citation can be traced to a crawl problem or a content problem?