Launching today

Maybloc
new SOTA for speech-to-text for multi-speaker audio
10 followers
new SOTA for speech-to-text for multi-speaker audio
10 followers
Speech-to-text built for conversations with more than one voice with highest accuracy than any in the industry. Lowest diarization error on several benchmarks. 45 languages, up to 25 speakers. Add-ons: subtitles, PII redaction, summaries, speaker names, translation. Better than Pyannote, Deepgram and Assembly AI


Hey Product Hunt, we're the team behind Maybloc.
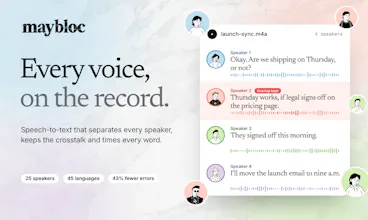
Most transcription tools handle one voice well and fall apart when people talk over each other. We built Maybloc for that case: every speaker kept apart, overlapping speech kept instead of dropped, every word timed.
Under it is Calico, our speech model, which builds on open research including DiCoW from BUT. On the public multi-speaker benchmarks we ran (NOTSOFAR, AMI, DiPCo) it has the lowest siarization (who-said-what) error of pyannote, AssemblyAI and Deepgram, and over 40% fewer errors than AssemblyAI and pyannote on NOTSOFAR's real office meetings. Tables and method: maybloc.com/#benchmarks
Use it in the dashboard or through a REST API. 45 languages, up to 25 speakers, files up to 3 hours, $0.006 per minute billed by the second. Add-ons: subtitles, PII redaction, summaries, speaker names, translation.
Try it on your messiest recording and tell us where it breaks. Happy testing!
Congrats on the launch!
Are podcast video files supported out of the box or do they have to be converted to audio files first before upload?
Thanks in advance.
@kyteinsky Yes, they are. They are auto-converted on upload. You can check it on maybloc.com. Happy tinkering!