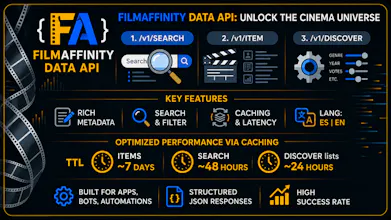
Most movie APIs ignore FilmAffinity or rely on broken scrapers. FilmAffinity Data API provides a stable, production-ready solution: -High Reliability: Smart caching and dynamic proxy rotation to prevent anti-bot breakage. -Rich Metadata: Clean JSON for search, detailed movie/series items, and custom discovery. -Dual Language: Full support in Spanish and English (lang=es|en). -Easy Setup: Standard schemas ready for bots, apps, and side projects with a free tier to test.
I needed FilmAffinity data for a personal cinema project. Quickly realized the painful truth: FilmAffinity has no official API, and almost every open-source scraper out there breaks within days because of anti-bot protections or random HTML changes.
I got tired of maintaining quick fixes, so I decided to build a proper, resilient backend for it: the FilmAffinity Data API.
A few things about how it works under the hood:
-Won't break randomly: Combines proxy rotation with smart caching. If scraping gets tricky, cached responses keep your app alive while issues get patched.
-The data you actually care about: Clean JSON for searches, full movie/series sheets, user & critic reviews, and streaming platform availability (supports both Spanish and English).
-Easy to test: Set up on RapidAPI with a free tier and an open Postman collection so you can run a query in 2 minutes without writing boilerplate.
If anyone could give me some feedback, I'd appreciate it. :)
Thanks in advance! :)
PD:
And for those who aren't familiar with Filmaffinity, it's like IMDb but specializes in the Spanish-language film community, boasting over 1 million users. It also supports English.


Hi guys!
I needed FilmAffinity data for a personal cinema project. Quickly realized the painful truth: FilmAffinity has no official API, and almost every open-source scraper out there breaks within days because of anti-bot protections or random HTML changes.
I got tired of maintaining quick fixes, so I decided to build a proper, resilient backend for it: the FilmAffinity Data API.
A few things about how it works under the hood:
-Won't break randomly: Combines proxy rotation with smart caching. If scraping gets tricky, cached responses keep your app alive while issues get patched.
-The data you actually care about: Clean JSON for searches, full movie/series sheets, user & critic reviews, and streaming platform availability (supports both Spanish and English).
-Easy to test: Set up on RapidAPI with a free tier and an open Postman collection so you can run a query in 2 minutes without writing boilerplate.
If anyone could give me some feedback, I'd appreciate it. :)
Thanks in advance! :)
PD:
And for those who aren't familiar with Filmaffinity, it's like IMDb but specializes in the Spanish-language film community, boasting over 1 million users. It also supports English.