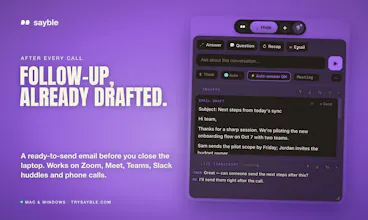
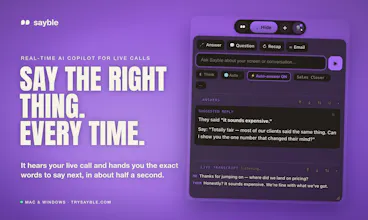
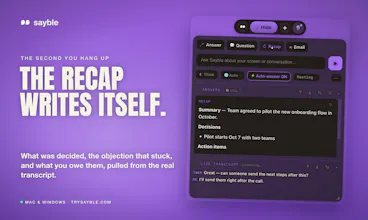
Sayble is a real-time AI copilot for sales calls, client meetings and negotiations. It hears what the other person just said and gives you one clear line to say next, plus a backup, in about half a second. When the call ends, it writes the recap and a ready-to-send follow-up email. Works on Zoom, Meet, Teams and phone calls. Mac & Windows, 10 languages.
hey PH, alexis here.
i built sayble because the best answer on a call almost always shows up after you hang up. on a sales call or a negotiation that's too late.
sayble listens to the live call and gives you one line to say next while they're still talking, then writes the recap and the follow-up when it ends. mac and windows, zoom/meet/teams/phone, 10 languages.
there's a free 3-minute live session, no card. i'd love to know where it breaks on your calls. i read everything.
Report
I heard something about a service like this one, and now is live. That's awesome, how the launch is going for your product?
@valentininventarqr thanks valentin. honestly the best part so far is people telling me where it breaks on their own calls. if you try it on a real one, tell me what it got wrong.
we build a voice API at Dial so the half-second number caught my eye. that's genuinely fast if it holds on real calls, but the number that usually breaks products like this isn't average latency, it's the tail - what happens on the 1 in 20 calls where the other person talks over the line, or there's a bad connection and transcription lags. does the model just stay quiet in that case, or does it sometimes suggest a line that's a beat behind what was actually just said? that mismatch is the scenario that actually loses deals, not the happy path.
@galdayan you're asking the right question. honest answer: it doesn't stream guesses, it answers the other person's last finished turn. so on crosstalk it waits for the turn to close instead of jumping in, and that wait is where the tail lives. the stale-line case you describe can happen when transcription lags behind a fast back-and-forth, and that's exactly the number i'm watching now, the slow 1 in 20, not the average. i'll share real p95s once there's a week of live calls behind them.



Sayble
I heard something about a service like this one, and now is live. That's awesome, how the launch is going for your product?
Sayble
@valentininventarqr thanks valentin. honestly the best part so far is people telling me where it breaks on their own calls. if you try it on a real one, tell me what it got wrong.
Sayble
we just finished our launch film, 35 seconds of what sayble actually does on a live call: https://youtu.be/AlR7r1Ac664
thanks to everyone who's tried it today. if it missed on one of your calls, tell me which moment. that's what i'm fixing next.
Dial
we build a voice API at Dial so the half-second number caught my eye. that's genuinely fast if it holds on real calls, but the number that usually breaks products like this isn't average latency, it's the tail - what happens on the 1 in 20 calls where the other person talks over the line, or there's a bad connection and transcription lags. does the model just stay quiet in that case, or does it sometimes suggest a line that's a beat behind what was actually just said? that mismatch is the scenario that actually loses deals, not the happy path.
Sayble
@galdayan you're asking the right question. honest answer: it doesn't stream guesses, it answers the other person's last finished turn. so on crosstalk it waits for the turn to close instead of jumping in, and that wait is where the tail lives. the stale-line case you describe can happen when transcription lags behind a fast back-and-forth, and that's exactly the number i'm watching now, the slow 1 in 20, not the average. i'll share real p95s once there's a week of live calls behind them.