
Invofox
The Document Parsing API for developers
429 followers
The Document Parsing API for developers
429 followers
Invofox is a document parsing API for software teams that turns complex, real-world documents into accurate, structured data. Built for high-variance workflows, Invofox goes beyond OCR with classification, validation, and extraction that scale reliably in production.
This is the 3rd launch from Invofox. View more

Invofox Self Serve
Launching today
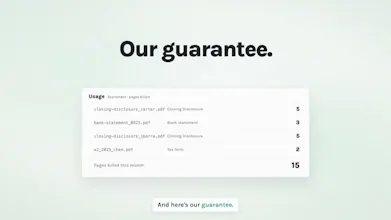
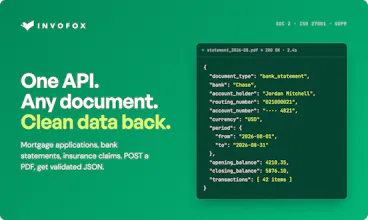
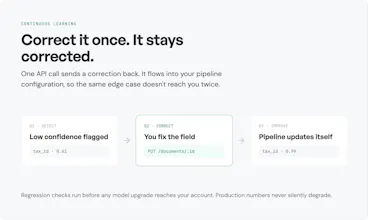
Invofox turns any document into clean, structured JSON through one API. Get 99%+ accuracy backed by SLAs. If we make a mistake, you don’t pay for that document. Invofox handles parsing, extraction, validation, edge cases, and monitoring behind one endpoint, then automatically learns from your feedback to keep improving on the documents your business actually processes.



Free Options
Launch Team

Framer AI AgentsDesign and publish professional sites with AI
Promoted

Hey Product Hunt 👋
We started Invofox because we kept watching good engineering teams lose entire quarters to document processing. The weekend prototype always works. Then come the scanned faxes, the multi-document PDFs, the tables that span three pages, the tax IDs that only appear in the footer, and suddenly two engineers are maintaining an OCR pipeline instead of building the product.
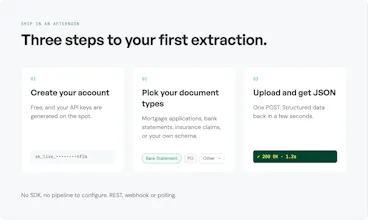
So we built the pipeline once, properly: intake, dual-pass OCR, splitting, classification, extraction, cross-field validation, confidence scoring, provenance, and a feedback loop that keeps improving on your specific documents. You POST a file to one endpoint and get validated JSON back.
For the last few years that only existed behind an enterprise contract. We were heads-down serving some of the largest tech companies and enterprises in Europe and the US, and honestly, we never built a way for a small team to just try it.
That always felt wrong.
Today that changes. Invofox Self-Serve is the same pipeline and the same accuracy bar, available with a signup form instead of a sales call. Two things we care about most: accuracy is part of our SLAs, and any document where we make a mistake is completely free. Pricing is per page, it goes down with volume, and there are no credit systems to decode.
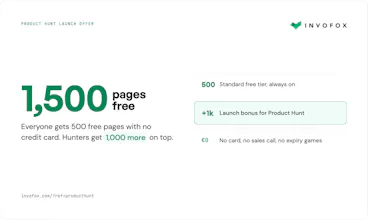
For Product Hunt: the free tier is 500 pages with no credit card, and we're adding 1,000 extra pages on top for anyone who signs up from here.
Bring us your worst document. The one that broke your last parser. We'd genuinely like to see it, and we'll be in the comments all day.
@alberto_gimeno getting clean JSON straight from a POST request saves so much boilerplate
@alberto_gimeno @priya_kushwaha1 Thanks Priya. Invofox's goal is to make document extraction so simple for technical teams that they can focus on their product roadmap and core features.
@alberto_gimeno @nachogabaldon that’s exactly the kind of simplicity that makes a real difference for technical teams..
Great idea :) Can I use it locally for sensitive information?
@alieksia yes, we support zero data retention and on premise deployments! Talk to our team and we'll be happy to help you with it
@alberto_gimeno How well does Invofox handle Messy or low quality scanned documents, that's usually where document parsing gets really difficult.
@alberto_gimeno @rohit62661 Hey Rohit! Totally agree, clean PDFs in tests never reflect real-world production. To tackle messy scans, we run a pre-processing pipeline first (orientation, deskewing, noise reduction and contrast enhancement) and then route the document through different OCR engines depending on its quality. We also use feedback from each client to fine-tune extraction over time. And to keep things fair, if we can't accurately extract the data you need, we don't charge for that document.
Great idea! Am I allowed to create my own schema for different types of documents or select predefined schemas such as invoices, receipts, and bank statements?
Additionally, Congratulations @nachogabaldon , @alberto_gimeno & team Invofox Self Serve ✌️🚀
@alberto_gimeno @aymi_malik Thanks a lot for the support! Yes to both! You can use our pre-built schemas for standard documents like invoices, receipts, and bank statements out of the box.
If you have custom layouts or specific fields you need to extract, you can also define your own custom schemas to fit your workflow.
@alberto_gimeno @nachogabaldon Thanks for Explaining :)
Putting a guaranteed SLA and a no pay on mistakes rule behind document extraction is a confident move, and it is the pricing model that made me look twice. Learning from feedback on the specific document types a business actually handles should help accuracy compound over time. Does the model get per customer fine tuned or does it stay shared?
@karimbenkeroum Hello Kareem. It's per customer, and that is very important decision. One client's data it never shared with other nor used to train or fine-tune their models. The pricing structure came very natural, it's the best way to align our technology with our clients needs