Launching today

TokenSpend
Route 120 models and see what every request cost
1 follower
Route 120 models and see what every request cost
1 follower
TokenSpend sends your LLM requests to 120 models from 21 vendors and returns a receipt for each one: model, tokens, cost and latency. It works with any OpenAI-compatible client, so switching models means changing the model name. Bring your own provider keys and routing is free, or buy credits at list price with a 5% fee. No markup on tokens, and we don't store prompts. For teams using coding agents, it also ties spend to the pull requests that merged.



Payment Required
Launch Team

AWS Activate CreditsCredits that fuel your startup’s next milestone
Promoted
Hi, I'm Rameel. We built TokenSpend because most AI cost tools show what you spent but not how much of it ended up in merged code.
You point an OpenAI-compatible client at one base URL, pick a model by name, and each request comes back with a receipt (model, tokens, cost, latency). We don't store prompts or responses.
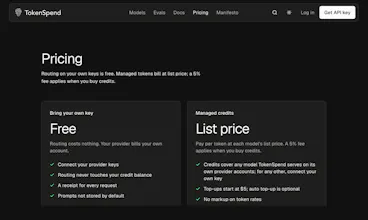
Bring your own provider keys and routing is free. Credits are billed at each model's list price with a 5% fee when you buy them. No markup on tokens.
It's for teams using several models, or coding agents like Claude Code, who want to see spend next to merged pull requests. We also ran first evals on Stagehand (12 merged PRs, 8 models, 7 agent harnesses, graded by each PR's own tests) and published the results.
I'd appreciate feedback: which models are missing for you, and what should a receipt show that ours doesn't?