
Prime Intellect
Commoditizing Compute & Intelligence
203 followers
Commoditizing Compute & Intelligence
203 followers
We're excited to announce our compute platform for aggregating and orchestrating global GPU resources. Our mission with our compute platform is to democratize and commoditize instant compute. H100s starting at $1.65/hr. A100s $0.87/hr. 4090s $0.35/hr.
This is the 3rd launch from Prime Intellect. View more

Prime Inference
Launching today
Prime Inference is Prime Intellect's serving platform for frontier open-source models, with serverless endpoints and reserved capacity across multiple datacenters on NVIDIA Blackwell GPUs. It's OpenAI compatible, fails over automatically between datacenters, and offers unified billing and team usage tracking. Its GLM-5.3 endpoint went live on OpenRouter on Sept 22 with a near-zero tool-call error rate and 100% uptime since launch, per Prime Intellect.




Free Options
Launch tags:Artificial Intelligence
Launch Team

Customer.ioAutomate Messaging Everywhere — Startups Get 12 Months Free
Promoted


Prime Inference is Prime Intellect's serving platform for frontier open-source models, with serverless endpoints and reserved capacity on their own GPUs across multiple datacenters.
Problem: Open models are only useful in production if they respond fast, stay up, and call tools correctly inside agents. Long agent sessions make this hard, since a typical turn adds about 6K tokens to a 140K-token prompt that reuses most of the conversation history. Many serving setups tuned for benchmark speed struggle with that kind of sustained, real-world traffic.
Solution: Prime built the serving platform it needed for itself, and it's now public. Before release it powered Prime's own large-scale RL rollouts, evaluations and long-running coding agents, processing nearly a trillion tokens a day internally. It has also served customer deployments in production since January.
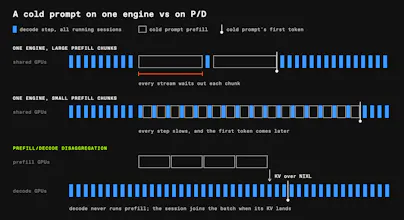
What makes it different: The post is open about the engineering behind it. Splitting prompt processing and token generation onto separate GPU groups cut p90 inter-token latency by nearly 40% in Prime's tests. A compressed cache format (NVFP4) gives about 50% more cache capacity per decoder. Prime also fixed a tool-call problem where calls to undeclared tools could be silently dropped, and contributed the fix upstream to NVIDIA Dynamo. The first public deployment, GLM-5.3, went live on OpenRouter on September 22. Prime says it's among the fastest GLM-5.3 endpoints there, with a near-zero tool-call error rate and 100% uptime since launch.
Key features:
Serverless endpoints for variable demand, reserved capacity for sustained workloads
OpenAI compatible, so you point existing SDKs at https://api.pinference.ai/api/v1, or use the prime CLI
Automatic failover across datacenters, with a 24/7 on-call team monitoring the hardware
NVIDIA Blackwell today, with Vera Rubin coming soon
Unified billing and team-level usage tracking across models
Built on NVIDIA Dynamo, vLLM, Mooncake and FlashInfer, with improvements contributed upstream
Who it's for: Teams running agents, coding assistants, evaluations or RL workloads on open models who need production reliability and don't want to run their own GPU fleet.
What's next: Batch and async inference for large offline jobs at lower prices, plus dedicated and 1-click deployments, including your own fine-tuned models from Prime training runs.