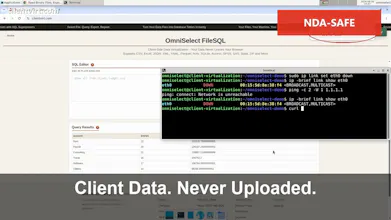
I'm the creator of ClientVirt. I built it for organizations that can't upload sensitive files to cloud AI or analytics services. ClientVirt runs entirely in the browser, keeping data on your device. Features: Natural language to SQL, local AI, no LLM APIs, zero network calls, no uploads, works offline, and supports CSV, Excel, JSON, JSONL, Parquet, Avro, SAS, SPSS, Stata, Access, BSON, MessagePack, CBOR, YAML, XML, Gzip, ZIP and more. I'd love feedback on usability, performance, and use cases.
I work with data in environments where uploading files to cloud services is often prohibited or heavily restricted. I kept seeing the same problem: people had CSVs, Excel files, Parquet files, SAS datasets, and databases they needed to analyze, but most modern AI and analytics tools required sending data to someone else's servers.
I started building ClientVirt to answer a simple question: could data exploration, natural language querying, and SQL analysis happen entirely inside the browser while keeping the data on the user's device?
The project evolved from a simple file viewer into a local-first analytics platform. Along the way I focused less on adding cloud features and more on removing dependencies, eliminating network calls, supporting additional file formats, and improving the natural language to SQL experience without relying on external LLM APIs.
Today the core idea remains the same: make data accessible without requiring users to give up control of where their data resides. I'd love feedback on performance, usability, supported formats, and real-world use cases.