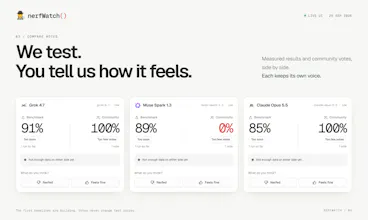
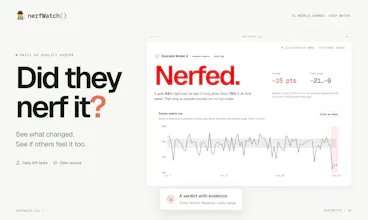
nerfWatch() tests AI models daily through their APIs, against each model's first week of tracking. See scores beside community votes, get alerts for declines and recoveries, and inspect the open-source engine. API tests, not chat-app tests.
Hi Product Hunt, meet nerfWatch().
When an AI model feels worse, one disappointing answer doesn't tell you much. nerfWatch() gives you a place to compare repeated tests with what people are experiencing.
Here's how it works:
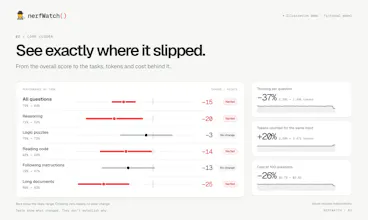
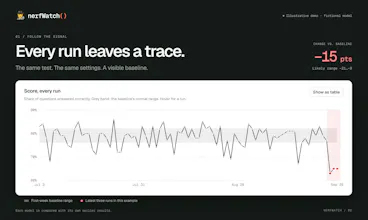
- Each tracked model takes the same 100 questions daily, across reasoning, logic, reading code, following instructions, and long documents.
- Answers are graded by code. Each model is compared with its own first 7 days of tracking, with model settings held fixed.
- Community votes sit beside the benchmark. You can vote once per model per day; votes never change the measured score or verdict.
- Email alerts report when a model enters the worse-than-baseline state or recovers.
- The testing engine is open source, so you can inspect it or run your own checks.
Tracking has just started: the initial baselines are still building, so there are no meaningful before-and-after verdicts yet. The dashboard shows "Too soon" while it collects that first week.
A few limits matter. These are API tests, not tests of ChatGPT, Claude.ai, or other chat apps. They cover a specific set of tasks, and a score change doesn't reveal why it happened. We also can't measure changes from before tracking began.
Take a look at https://nerfwatch.lol and share what you think. Which model should be tracked next, and what kind of test would help you trust the result?


Burner Mail