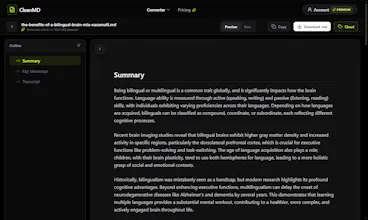
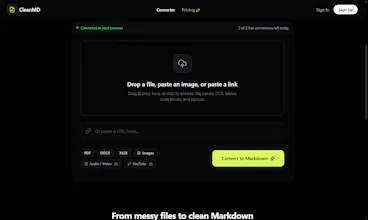
CleanMD turns messy files into clean Markdown PDF, Word, Excel, images, even scans. AI reads charts and equations too. Premium transcribes audio/video/YouTube and connects Drive & OneDrive. Files never leave your browser.
Hi hunters! 👋
I built CleanMD because every "X to Markdown" tool I tried failed the same two ways: it flattened the document structure (goodbye headings), or it choked on anything that wasn't a native PDF.
CleanMD is different in five ways:
1. Structure is the product. Heading hierarchy (H1/H2/H3), tables, lists and reading order are preserved it's what makes the output actually usable in Obsidian, Notion or an LLM context window.
2. Privacy by architecture. Documents convert in your browser they never touch our servers. Scanned PDFs go through an EU OCR engine with contractual zero data retention (free tier included); audio/video are processed server-side but deleted the moment your Markdown is ready. Nothing is ever stored.
3. It reads what OCR can't. Charts and figures inside documents get described inline with abstention built in, so it never invents numbers it can't read; display equations come out as LaTeX (rendered live in the preview).
4. It checks its own work. Every conversion is validated before delivery (content lost vs the source, tables that are actually code, broken Markdown): what can be repaired deterministically is repaired, and you get an honest warning for the rest never a silently broken file.
5. It listens and it's plugged in. Premium transcribes audio, video and YouTube links (even without captions) into structured notes with timestamps and speakers, and converts straight from Google Drive or OneDrive, saving the .md back where the source lives.
Free tier: 3 conversions/day, no signup.
Don't take my word for the structure claim: I published a benchmark against MarkItDown and pymupdf4llm on five public PDFs (an RFC, a two-column paper, a 292-page textbook, a Supreme Court opinion, a NIST standard), scored against the documents' own tables of contents, with the kit to rerun it — losses included (the first run had pymupdf4llm ahead on RFC section recall; the fix and the history are on the page): https://cleanmd.dev/benchmarks/p...
I'd love your feedback especially on documents that break it. Ask me anything!