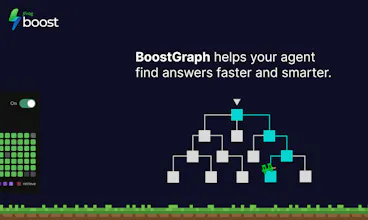
Boost is a free, local-first CLI that compresses noisy tool output before it reaches Cursor, Claude Code, Codex, or GitHub Copilot. Save tokens without changing workflows. Instead of blind truncation that breaks agents, Boost uses a shift-right, retrieval-backed approach. If your agent truly needs the raw logs, it can fetch them instantly. Standout features include: 1. Context-Aware Noise Compaction 2. BoostGraph 3. File Optimization 4. Agent Observability & Telemetry 5. Enterprise-Grade Privacy
We built Boost after hitting $700+ Cursor bills and $1,700+ Claude Code sessions in our R&D org at JFrog. Tracing those soaring token costs led us to one huge culprit: our AI agents were swallowing massive amounts of irrelevant context on every single prompt turn - test logs, progress bars, and verbose CI outputs, all charged at premium token rates.
We realized ~90% of what we were paying for was pure noise. Boost uses multiple techniques to strip out the fluff before it hits the API, making your agents faster, cheaper, and smarter. Best of all, it eliminates "agent amnesia." If the model hits a roadblock and actually needs full output to debug, our retrieve feature instantly fetches the raw, unfiltered logs from local history.Everything runs locally to keep your code private, with only minimal, anonymous telemetry to help us crush bugs.
Boost already saves over 1 trillion tokens every month for tens of thousands of developers and vibe coders worldwide, without compromising on the agent response quality.
Today, we’re opening it up completely free to the community!
It’s backed by real benchmarks, with every feature battle-tested on 1,500+ developers at JFrog before rolling out.
We’d love your honest feedback! How are you currently keeping your agent context lean without breaking your dev workflows?
Report
I’ve been using this product as an early adopter (I’m from JFrog), and I think it’s amazing.
Yeah, I’m biased 😄 so don't just take my word for it, try it yourself!






Hey Product Hunt! @yahav_ohana and @shay_dahan here, the builders behind Boost.
We built Boost after hitting $700+ Cursor bills and $1,700+ Claude Code sessions in our R&D org at JFrog. Tracing those soaring token costs led us to one huge culprit: our AI agents were swallowing massive amounts of irrelevant context on every single prompt turn - test logs, progress bars, and verbose CI outputs, all charged at premium token rates.
We realized ~90% of what we were paying for was pure noise. Boost uses multiple techniques to strip out the fluff before it hits the API, making your agents faster, cheaper, and smarter. Best of all, it eliminates "agent amnesia." If the model hits a roadblock and actually needs full output to debug, our retrieve feature instantly fetches the raw, unfiltered logs from local history. Everything runs locally to keep your code private, with only minimal, anonymous telemetry to help us crush bugs.
Boost already saves over 1 trillion tokens every month for tens of thousands of developers and vibe coders worldwide, without compromising on the agent response quality.
Today, we’re opening it up completely free to the community!
It’s backed by real benchmarks, with every feature battle-tested on 1,500+ developers at JFrog before rolling out.
We’d love your honest feedback! How are you currently keeping your agent context lean without breaking your dev workflows?
I’ve been using this product as an early adopter (I’m from JFrog), and I think it’s amazing.
Yeah, I’m biased 😄 so don't just take my word for it, try it yourself!