
EchoCache
Stop paying twice for identical LLM queries
3 followers
Stop paying twice for identical LLM queries
3 followers
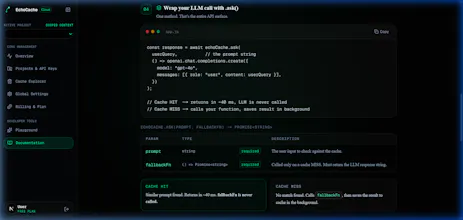
Ultra-low latency semantic caching layer for OpenAI, Anthropic, Gemini, and open-source LLMs. Reduce API bills by 80% and accelerate responses to <30ms.


Free Options
Launch Team

Render: Get up to $100K in startup creditsCloud infrastructure for founders who want to move fast and NOT break things
Promoted
