Statewave
Open-source memory runtime for production AI agents.
5.0•15 reviews•88 followers
Open-source memory runtime for production AI agents.
5.0•15 reviews•88 followers

88 followers
88 followers
Statewave is an open-source, self-hosted memory runtime for AI agents, with a governance layer most tools ignore.
Right now, memory in agents is a black box:
- no auditability
- no control over what s stored
- no way to debug why an agent remembers something
Statewave tries to fix that.
You can run it locally in ~2 minutes:
npx @statewavedev/statewave
It plugs into Claude Code, Cursor, VS Code Copilot and other MCP clients. No account. Works offline. I ll be around in the comments on launch day, curious what feels broken, over-engineered, or unnecessary.
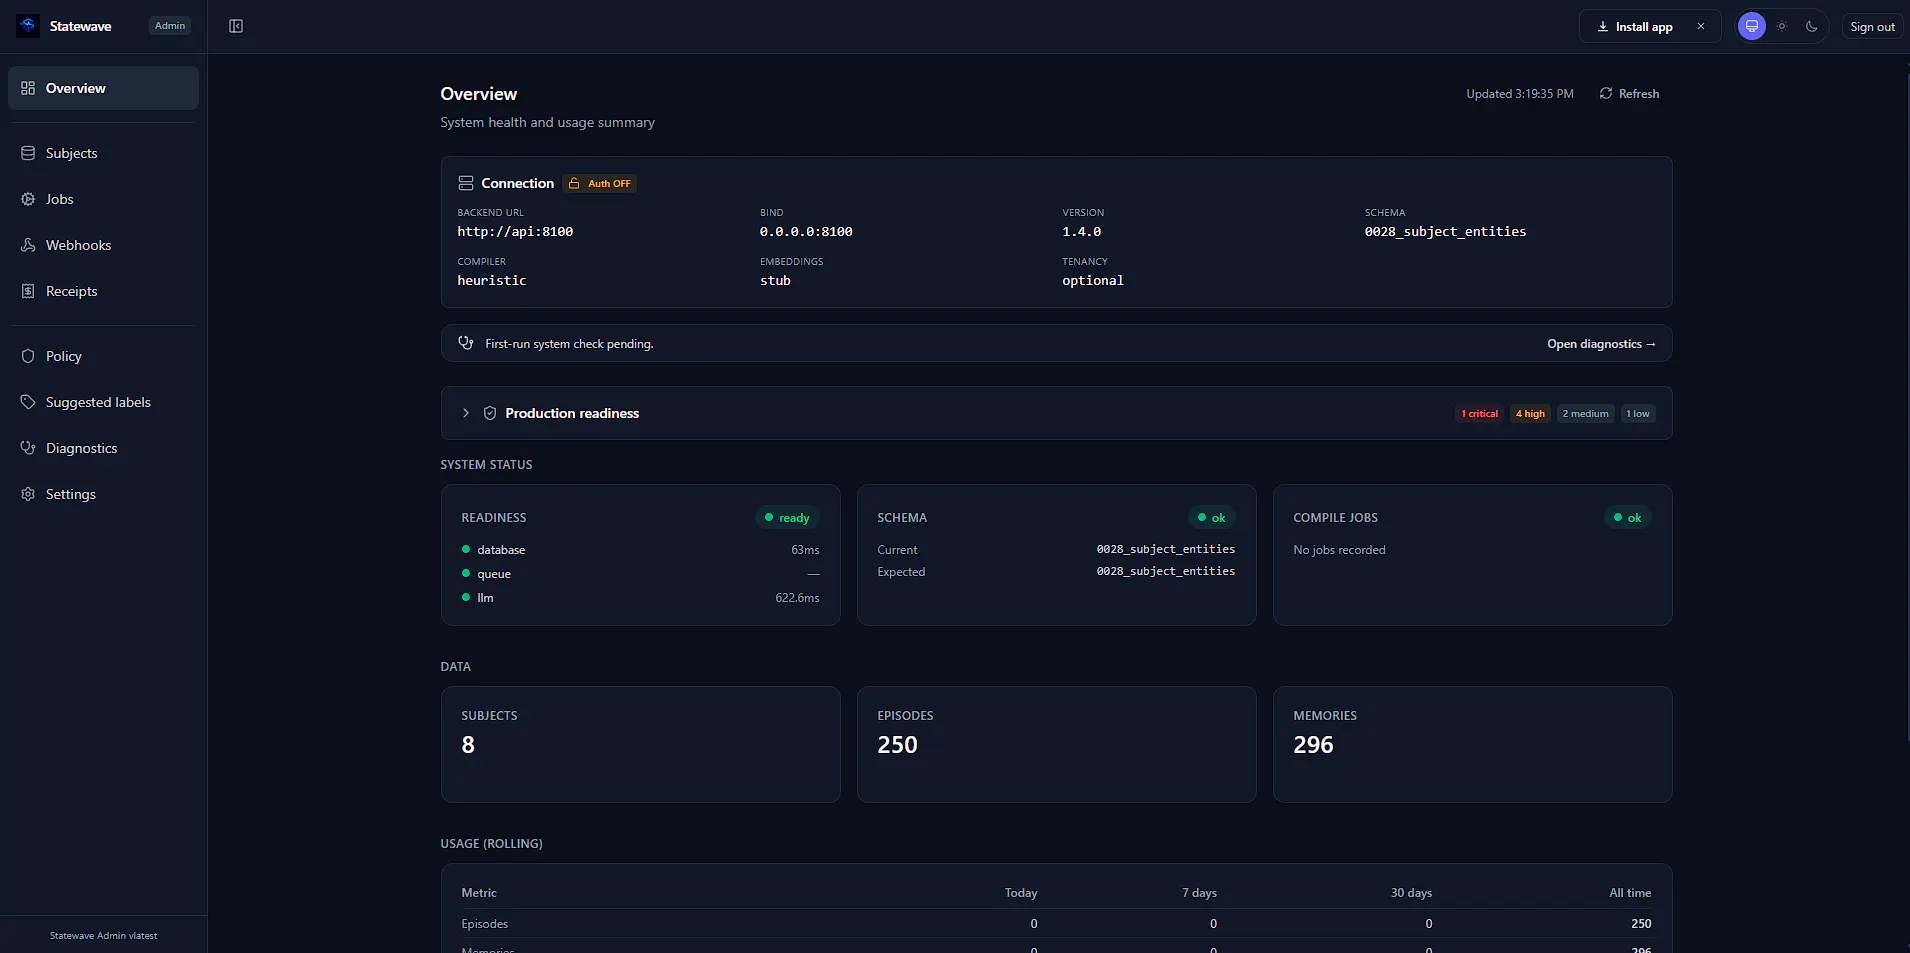
The screenshot below is the part of the admin console I get asked about most.

We're getting ready to launch here, and I'd rather use this thread properly than just show up on launch day.
Short version: Statewave is an open-source memory runtime for AI agents. Self-hosted, Apache 2.0.
The problem we kept running into: agent memory is usually just a vector store. It hands back text ranked by similarity, and that's it. The moment an agent sits in front of real users, someone asks: where did that come from? Who was allowed to see it? Has it been changed? A similarity score answers none of those.
So we treat memory as infrastructure instead. Access policies, sensitivity labels, tamper-evident audit receipts, and provenance on every memory back to the episode that produced it.
Dead simple to set up. One command and it's running. No painful config, just works. Self-hosted, you own your data, governance is actually there. Free and open source too.
Docs could use more real examples
Most memory stuff is just vector stores. I needed something where you can actually see what's being remembered and control who accesses it.
Found Statewave while looking for a memory solution for a multi-agent setup I was building. Most of what I tried either used vector stores with zero visibility into what's actually being remembered, or required me to build the whole governance layer myself. Statewave was running in under 5 minutes, self-hosted on Postgres, and the provenance tracking was there out of the box, not something I had to wire up manually.
The thing that actually stuck with me was how clean the access control is. I'm working across a few different projects with different sensitivity levels, and being able to set tenant isolation without fighting the tool to do it is genuinely rare. Context persisting properly between sessions has already saved a noticeable amount of time, no more re-explaining architecture decisions every time a new conversation starts.
Docs need more end-to-end examples for real use cases, not just basic setup. The admin dashboard is functional but pretty minimal right now, more visibility into what's stored and who's accessing what would help a lot, especially for team use. A cloud-hosted option for teams that want shared memory without managing their own infra would also be a big unlock.
Tried a couple of managed memory services before this. The permission models were weird and opaque, and I didn't love the idea of sensitive project context sitting on someone else's infrastructure. Vector stores were the other option but they don't track decisions or preserve the kind of structured context I needed. Building it from scratch was on the table for about a day before I decided it wasn't worth the months it would take.
This might be the most useful review we've had all day — thank you, Nolan. You've put your finger on exactly the hard parts: tenant isolation across projects with different sensitivity levels was one of the trickiest things to get clean, so hearing it held up in a real multi-agent build means a lot.
And your improvement list is spot-on — more end-to-end doc examples, deeper visibility in the admin dashboard for team use, and a shared/hosted option so teams don't run their own infra. All three are exactly where we're heading. If you're open to it, I'd genuinely like to hear more about your multi-project setup as we build those out — that's the feedback that shapes them right.
Using it for a multi-session coding agent. Tech stack, decisions, architecture preferences actually persist between conversations. No more explaining context every session. Self-hosted so code stays private.
Vector stores don't track decisions or preserve project context properly. Building memory manually was too much work.
Love this — the multi-session coding-agent case is one of our favorites: tech stack, decisions and architecture choices persisting so you stop re-explaining context every session, and self-hosted so the code stays private. "Building memory manually was too much work" is basically why Statewave exists.
Thanks for both the review and the hosted-version question earlier — you're clearly putting it through real use, which is exactly the feedback we want. If anything comes up as the project grows, we're around.
Hey Product Hunt 👋
I’m Saber Maram, the creator of Statewave.
Most AI agent memory today is essentially a black box: a vector store gives you “relevant” context, but it’s hard to know where that memory came from, who can access it, or whether it was modified.
That works for demos. Production systems need more.
So we built Statewave, an open-source, self-hosted memory runtime designed around governance from day one:
🔐 Access policies & sensitivity labels to control what agents can read/write
🧾 Tamper-evident audit receipts for verifiable memory history
🔍 Source traceability so every memory can be traced back to its origin
⚡ One-command local deployment with the API, admin console, and PostgreSQL included
You can run it locally with:
npx @statewavedev/statewave
It takes about two minutes and works with tools you already use, including Claude Code, Claude Desktop, Cursor, VS Code Copilot, Zed, Aider, Windsurf, and other MCP-compatible clients.
No account. No hosted dependency. Your data stays on your infrastructure.
We also wanted governance to come without sacrificing memory quality. On mem0’s own benchmark harness, Statewave outperforms mem0’s open-source version on both LoCoMo and LongMemEval, while matching its paid cloud tier. The benchmark results are fully reproducible:
https://www.statewave.ai/benchmarks
And this isn’t a launch-day prototype. Statewave is now at v1.4.0, with 384 commits, 14 releases, 10 contributors, 306 GitHub stars, and 10.3K Docker pulls, with 708 unit tests and 56 eval assertions running in CI.
Everything is open source under Apache 2.0:
https://github.com/smaramwbc/statewave
More about the project: https://statewave.ai
If you’re running AI agents in production, I’d especially love to hear:
What’s your biggest memory or governance pain right now?
We’ll be around in the comments today.
@statewavedev @saber_maram Outstanding launch, Building a governance-first memory runtime addresses the exact missing layer in modern agent architecture.
@statewavedev @priya_kushwaha1 Thanks Priya 🙏 That "missing layer" is exactly it — retrieval got solved, governance didn't. Curious from what you've seen: is the bigger gap usually access control, or provenance/auditability?
@statewavedev @saber_maram Nice launch Congrats 🙌trying to answer your q: our biggest pain right now is multi-agent collision two agents reading/writing conflicting state to the same session. Does Statewave provide Python and TypeScript SDKs for custom agent frameworks alongside standard REST APIs?
@statewavedev @vikramp7470 Great question — that's a pain we designed directly for. Two agents writing conflicting state to the same session is handled at two layers:
1) Writes are append-only episodes with idempotency keys, so concurrent or duplicate writes don't silently clobber each other — nothing gets overwritten.
2) When two writes genuinely conflict, compilation resolves it by supersession: the newer memory supersedes the older, but the older isn't deleted — it's kept as "superseded" with provenance links to both, so you can always reconstruct what changed and why. No last-write-wins data loss.
On the SDKs: yes — both Python and TypeScript SDKs, alongside the standard REST API and an MCP server, so you can wire Statewave into custom agent frameworks directly. Happy to point you at the right one for your stack.
What framework are you building on? That multi-agent-collision case is one we'd love to get right for you.
@statewavedev @saber_maram Appreciate the clear explanation! Supersession with full provenance history completely solves the last-write-wins headache. we're on Python with LangGraph. Awesome to hear the Python SDK is ready to go diving into the docs now.. all the best for launch🙌
@statewavedev @vikramp7470 Love it — LangGraph + Python is a great fit. The Python SDK drops straight into your graph nodes (call it wherever you read/write state), with the REST API + MCP server there if you ever want it out-of-process. If the docs feel thin on a LangGraph-shaped example, that's exactly the gap we want to close — ping us or open a thread in Discussions and we'll help you get the first memory flowing. Thanks for the kind words, and enjoy the dive 🙌
@tehreem_fatima5 Thanks Tehreem 🙏 The npx setup was a deliberate bet — testing should be a 2-minute thing, not a weekend. Appreciate the kind words and the support today!
@istiakahmad Congrats-back 🙏 Yes — that's exactly what the admin console is for. A subject explorer lets you browse and drill into per-subject memories and episodes, inspect provenance, state-assembly receipts, sensitivity-label policy and compile-job health — and manage compiled memories directly (edit/invalidate), no raw SQL against Postgres.
If your operators prefer the terminal, there's a CLI with full parity — every operation the web UI does. It's a privileged, secure-by-default console (password gate + access gateway), meant to run against your own instance.
This is the repo: https://github.com/smaramwbc/statewave-admin
What's your operator workflow — mostly audit/inspect, or hands-on correction?
@arvish_suresh Great question. Short answer: self-hosted + open source stays the core — that's the whole point (own your data, inspect the governance yourself, no phone-home), and it's not going anywhere.
That said, yes — a managed/hosted option is on the roadmap for later, for teams who'd rather not run the infra themselves. The important part: the OSS won't turn into a crippled "community edition" to push people to cloud. Self-hosted stays fully supported and first-class.
Out of curiosity — is it mainly the infra/ops overhead you'd want to skip, or something else? That helps us shape what the hosted version should prioritize.
@arvish_suresh Thanks for the review and the hosted-version question, Arvish. I'll keep you posted as the managed option firms up. In the meantime, if anything comes up with the multi-session coding setup, I'm around.
Been using Statewave for a multi-agent setup — the supersession model is the part that sold me. When two agents write conflicting state, the older one isn't dropped, it's kept as superseded with links to both. Curious how you're thinking about surfacing those conflict chains in the console over time?
@abhi_singh4000 Thanks - that's where we build the https://github.com/smaramwbc/statewave-multi-agent-memory for. Allways open for any comments on it.
What got me was traceability. In my own agent project I could never answer "why did it use that memory?" — just a similarity score. With Statewave every retrieval traces back to a source, and the receipt shows what actually went into the context. That's the piece I'd been building badly by hand.
@rajesh_gupta__ Facing the same problems is why we build this. Share your experience we are open for all response.


Thanks Sid — "one command and it's running" was exactly the bar we set, so glad it held. And you're right on the docs: more real, end-to-end examples is genuinely near the top of our list. If there's a specific workflow you were setting up, tell us — we'll prioritize that one first.